Structured Data Feeds vs Unstructured Web Retrieval for AI Agents
Architectural choices about where AI agents fetch facts matter more than which model processes them.
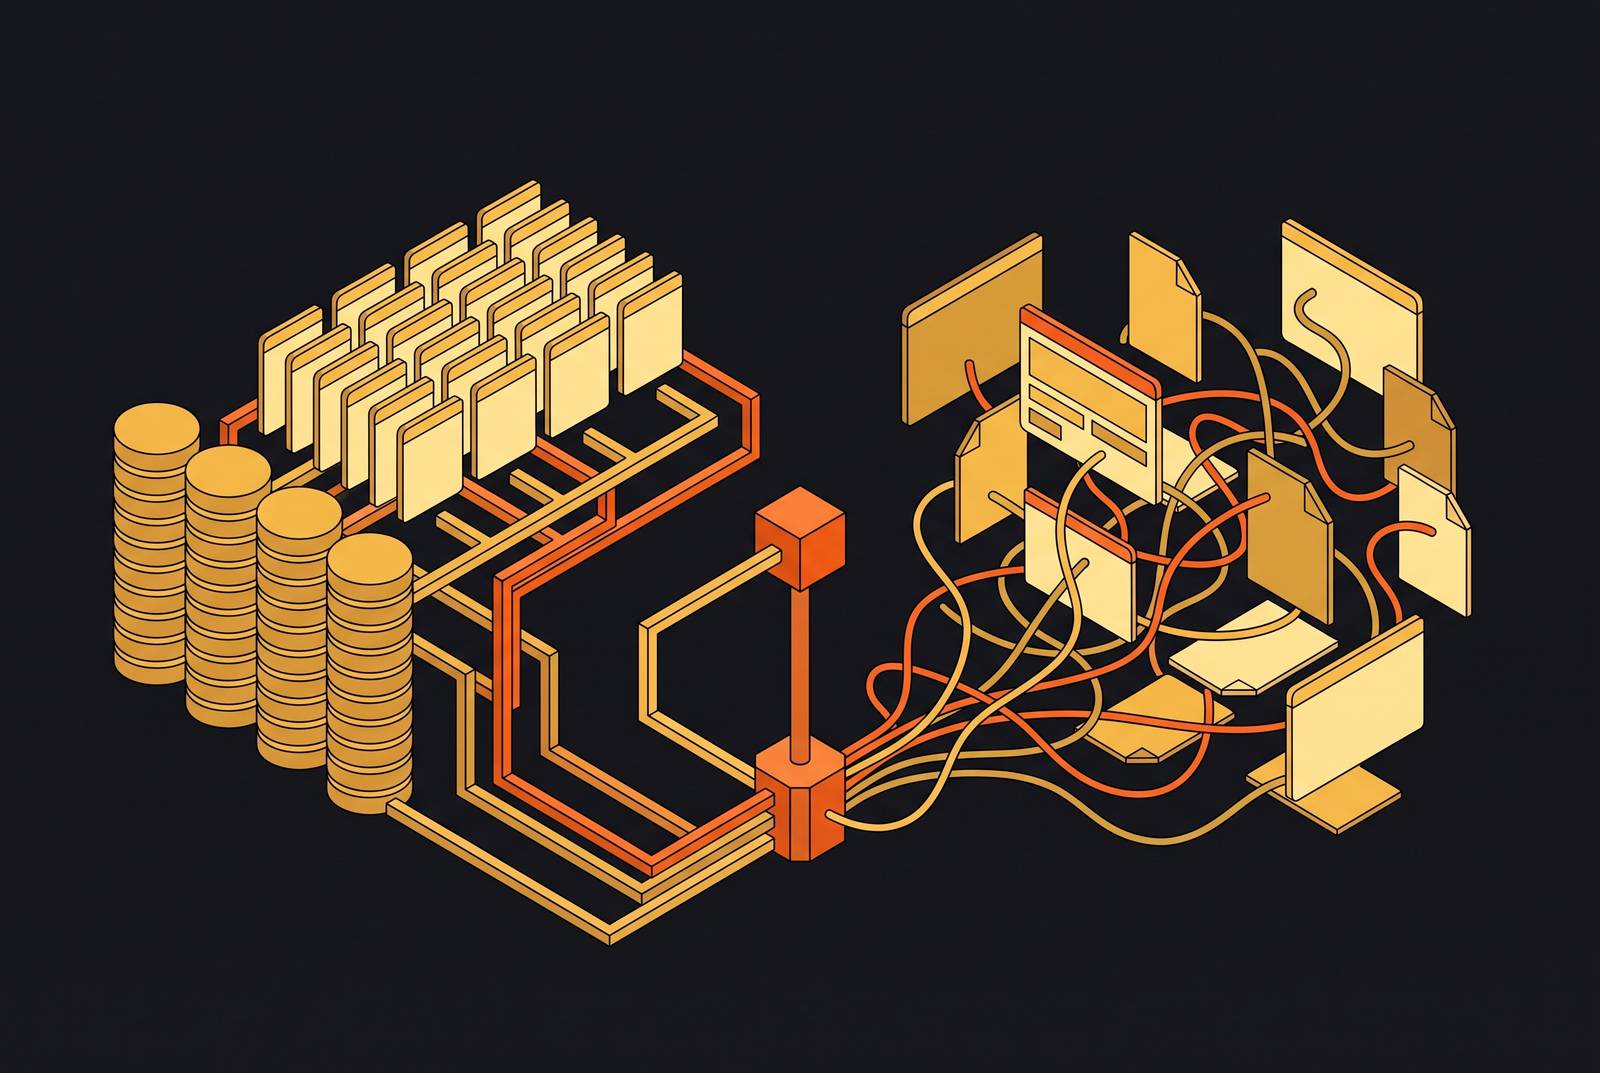
Stopping a production language model from citing outdated facts means giving it a retrieval path to live web content, not just a bigger training set or a better prompt. The fix is architectural: pair a structured data feed for facts that must be exact with a live web retrieval layer for facts that change by the week, and route queries to each based on what the question actually needs. No single data source, however current at ingestion, stays current forever, and the choice of where an AI agent looks for an answer now carries as much engineering weight as the choice of which model answers it.
Why retrieval source design is a first-class engineering decision
Large language models carry two failure modes by design. Their knowledge freezes at a training cutoff, and when the context they're given is missing or stale, they tend to produce answers that sound right and aren't. Retrieval-augmented generation was supposed to fix this by pulling in current documents at query time, but it doesn't remove the risk so much as move it. The model stops guessing blind and starts trusting whatever gets handed to it, so the retrieval layer becomes the place where correctness actually gets decided.
The 2026 AI Agent Architecture guide from EICTA/IIT Kanpur lays out a production agent as four connected layers: reasoning, orchestration, memory and data, and tool integration. Retrieval source decisions live in the memory and data layer, and a weak choice there can't be patched over by a stronger model sitting in the reasoning layer on top of it. A team can swap in the best available model and still ship a system that confidently states last quarter's regulatory threshold as current fact, because the problem was never the model's reasoning. It was what the model was fed.
Picking between a structured data feed and open web retrieval isn't a matter of taste or a default setting teams fall into. It carries measured costs in freshness, in reliability, and in how hard a failure is to trace back to its source once it happens in production. Teams that treat the two as interchangeable, or lean on one without understanding where the other actually fits, end up with pipelines that fail in ways that are genuinely difficult to diagnose: the system looks healthy, the citations look plausible, and the fact underneath is simply wrong. Structured feeds and live web retrieval are complementary tools with different jobs, not rival philosophies competing for the same slot. Knowing exactly where each one breaks down is the skill that separates a demo that works in a conference room from a system that holds up under real production traffic.
How AI agents consume knowledge at runtime
An agent in production doesn't pull from one data source. It draws on a layered memory system plus a set of retrieval calls made at the moment a query arrives, and each layer behaves differently on freshness, latency, and reliability. The EICTA architecture splits this into a reasoning layer, an orchestration layer, a memory and data layer that spans both short-term context-window memory and longer-term vector-database storage, and a separate tool integration layer the agent uses to call outside APIs and data services as the task requires.
A knowledge agent doesn't just fetch a matching document and hand it over. ValueStream AI's 2026 knowledge management guide describes an agent that reads the intent behind a query, walks a knowledge graph to find related concepts, weighs conflicting sources against each other with confidence scoring, and builds a cited answer from the result. Retrieval, under that description, is the substrate the thinking runs on.
Most production failures in agent systems trace back to this step, not to the generation that happens afterward. The source and shape of what gets retrieved matters as much as which model does the reasoning. The EICTA guide states the underlying principle: a powerful model sitting inside a badly designed architecture will fail consistently, while a well-designed architecture running a merely capable model can still deliver reliable results. The architecture carries more of the weight than the brand name on the model.
What structured data feeds do well
Some facts have to be exact, and for those, nothing beats a structured, governed source. A regulatory threshold, a contract penalty clause, a business definition that compliance has signed off on, a price list: none of these can responsibly come from a web crawl, because a crawl has no way to guarantee it found the current, authoritative version of anything. That's the clearest statement available of where structured feeds beat unstructured retrieval.
Semantic search returns text that resembles the query. It doesn't check whether that text is still the current, authoritative version of anything. A compliance agent can pull up a regulatory page that was superseded months ago, score it as a strong semantic match, and hand back a confident answer that happens to be wrong, with no signal anywhere in the output that anything went wrong. ValueStream AI's 2026 guide adds full source tracking and governance: provenance logging, permission-aware access, and audit trails built into the system. Structured feeds come with this kind of tracking natively. Bolting the same guarantees onto raw web content afterward is possible, but it's expensive and it's retrofitting, not design.
What makes this work at the ingestion stage is enrichment: attaching the source URL, the author, the last modified date, a classification, and access permissions to every chunk of content before it ever gets stored. That metadata is what lets a system filter results, check freshness, and enforce access control the moment a query comes in. Raw web content doesn't arrive with any of that attached by default; someone has to generate it. The practical move here is to map every query type an agent handles against the kind of knowledge it needs before deciding how to retrieve it, and to flag which of those queries demand an answer that is simply correct. A question like "what is the current AML threshold?" belongs in a structured feed. A question like "what is the market saying about this technology today?" belongs somewhere else. For the first category, a structured feed is the only correct option.
Where structured feeds break
A structured feed can only represent what someone already decided to put into it, and that's exactly where it runs out of road: anything recent, anything external to the organization, anything outside the governed corpus simply doesn't exist as far as the feed is concerned. An LLM's own knowledge freezes at its training cutoff, leaving it blind to anything that happened after. A structured feed inherits the same blindness in a different form. The horizon just moves forward to whenever the feed was last updated.
The EICTA guide treats on-demand context retrieval, including live web lookup, as its own distinct layer for exactly this reason: preloaded memory and static feeds can't stand in for live information when the task genuinely calls for it. The limitation here is structural, built into how a feed is constructed. A feed only contains what someone decided to include, and that decision always lags behind events in the world. Competitive intelligence, a regulatory change announced yesterday, technical documentation published this morning: all of it sits outside the fence by construction, not by accident. For a query about what a competitor said this week or what a regulator just published, a structured feed's answer is whatever it last indexed, which is not the same thing as the truth.
What makes this failure mode genuinely dangerous is that a stale structured feed doesn't look stale. It produces the same confident, well-formatted answer it always does, and the governance apparatus that makes it trustworthy for authoritative facts is the same apparatus that hides staleness from the agent consuming it. A governed definition pulled from a semantic layer carries certification markers: an owner, a version number, an approval stamp. An agent reads those markers as signs of authority. If the underlying definition was certified before a regulatory change took effect, those markers still fire exactly as they would for a current fact, and the system delivers a wrong answer wrapped in every signal of trustworthiness it has.
What live web retrieval solves and introduces
Live web retrieval is the only mechanism that can ground an agent's reasoning in facts that postdate any governed corpus the organization has built. It also brings in noise, inconsistency, and a security exposure the moment it's deployed without the right handling. Web grounding closes the gap that neither an LLM's frozen training data nor a static structured feed can close on its own: a live retrieval call can reach a page published minutes earlier, from a source nobody at the organization ever thought to add to an index.
Three structural problems come bundled with that advantage. Noise shows up because HTML parsing breaks whenever a site changes its layout, and fields extracted from different sources rarely come out in a consistent shape. Staleness persists even within a single crawl cycle, since data that was accurate at the moment it was scraped can sit for hours or days before it reaches the model, depending on how often the crawl runs. The same source can yield a different schema each time it's fetched across runs. When raw scraped content gets dropped straight into a prompt, the model is left to handle missing fields, mismatched formats, and outdated values on its own at inference time. That work used to belong to an upstream pipeline. Now it burns tokens and degrades the quality of whatever reasoning comes after it.
There's a security dimension too. The Agentic Web paper and the AI-Native Internet paper both establish that a malicious web page can be retrieved and have its embedded instructions executed as though they were legitimate commands from the user. Prompt injection through retrieved content is a live attack surface in any system that feeds raw web pages to a model without filtering first.
Preparing unstructured web content for an agent takes an investment that matches the governance work a structured feed demands. It's not a smaller cost, just a different one. Generic SERP APIs and scraping tools return raw HTML bundled with metadata an LLM agent still has to parse before it can reason about anything, and that parsing overhead eats tokens, adds latency, and introduces a failure mode that gets worse as web layouts keep changing. The retrieval layer, whether it's a structured feed or an unstructured crawl, decides not just how fast an agent gets an answer but how trustworthy that answer's grounding actually is. Infrastructure built specifically to serve an AI agent's retrieval needs, delivering content that's already filtered, ranked, and shaped for reasoning, has become a production concern. Seltz was built to close that specific gap: a web search API that owns its data pipeline end to end and delivers context-engineered, machine-ready content, filtered and ranked for a model's reasoning.
Why retrieval accuracy depends on hybrid search
Semantic vector search fails in production for a simple reason: similarity isn't the same thing as correctness. An agent can pull back text that matches a query closely and still generate a wrong answer if that text happens to be outdated or no longer applicable. The person asking the question has no way to tell the difference from the outside.
The fix that actually works combines two retrieval methods. ValueStream AI's 2026 guide goes a step further and names three components a production-grade retrieval engine needs: dense vector search for semantic matching, sparse keyword search through BM25, and graph traversal for questions that require connecting several hops of related information. This combination works the same way whether it's applied to structured feed content or to preprocessed web content, so source type and retrieval method need to be treated as two separate decisions.
Chunking strategy carries the same weight across both source types. That cost lands the same way whether the corpus is a structured feed or a preprocessed index of web content. The real design question sits upstream of the structured-versus-unstructured choice, not as a replacement for it. A team that picks the right source but bolts on a naive retrieval method will underperform a team running either source type through a properly engineered hybrid retrieval stack.
Enterprise access control at the retrieval layer, not after it
Access control tends to fail at the retrieval layer in enterprise AI systems, and trying to patch it after retrieval has already happened is both slower and considerably riskier than building entitlements into the retrieval query from the start. ValueStream AI's 2026 guide describes a production knowledge architecture as requiring a source tracking and governance layer with permission-aware access built in. A structural property of the retrieval interface itself is what enforces this: a user who lacks permission to read a document should never see that document show up in the AI workload's retrieval results.
The failure mode that follows from skipping this is architectural, rooted in how the retrieval index was built. A model can follow every instruction it's given and still expose information a user shouldn't see, because the leak originated in an index that never checked document permissions to begin with, not in anything the model itself did wrong. Safety measures built into the model can't substitute for access control enforced at the retrieval layer. Identity-aware retrieval bakes the permission check directly into the vector query before results come back. Filtering after the fact is slower and more dangerous, because a single misconfiguration can expose sensitive content before any downstream filter has a chance to catch it.
The same enrichment step described earlier, attaching classification, access permissions, and owner metadata to every chunk at ingestion, makes retrieval-time access control possible for structured feed content. Web content pipelines don't inherit any of that metadata automatically; it has to be generated. The retrieval interface needs to attach metadata like source, recency, authority, and confidence to whatever it returns, so the reasoning layer downstream has something to weigh and rank facts against. That kind of metadata richness is what separates retrieval pipelines built specifically for AI reasoning from general search tools designed for people browsing results by eye. Seltz treats data ownership and enterprise-grade security alignment as core design concerns in its own web search infrastructure, which matters here because teams running live web retrieval in production need the same governance guarantees they already expect from their internal structured data, guarantees that generic scraping tools generally don't provide.
A decision framework for choosing source type by query regime
The right source for a given query comes down to three properties: how fresh the answer needs to be, how authoritative it needs to be, and how broad the search for it needs to range. Most production pipelines need different answers to that question for different queries running through the same agent, not one fixed answer for everything. Questions that need current, external information, competitive intelligence, breaking news, technical documentation published hours ago, real-time market signals, belong in live web retrieval instead, because a structured feed cannot reach content it was never built to index, and the lag built into any indexing process makes it wrong by design for this entire class of question. Questions that require tracing a concept across many related pieces of internal knowledge belong in a knowledge graph layer running hybrid retrieval, since graph traversal is the piece that answers "what else in our corpus connects to this?" in a way that neither plain vector search nor web retrieval can manage on its own. The query-to-source map needs to live as shared infrastructure across an agent fleet rather than as a setting configured separately inside each one.
Each of these choices comes with an obligation attached, and neither one is the cheap option, they just place the work in different spots. Choosing a structured feed means building a governed ingestion pipeline (extraction, cleaning, chunking, enrichment), a semantic layer with named owners and versioned definitions, and access control enforced at retrieval time. Choosing web retrieval means building preprocessing that turns raw pages into clean, ranked, machine-ready content, filtering that screens out adversarial material, latency management for calls made in real time, and citation tracking so the reasoning layer can say where a given claim came from. The case for purpose-built web search infrastructure, rather than wrapping a generic search API or standing up a scraper in-house, is that it moves the preprocessing burden off the AI team and onto infrastructure built for exactly that problem. Seltz's approach, owning the data pipeline end to end to deliver content that's already ranked and filtered for AI reasoning, is what that obligation looks like once a team decides to treat it as a systems design problem.
The place to start is mapping every query type an agent handles against freshness, authority, and breadth before any retrieval infrastructure gets built, with a plan from the outset to route different queries through different sources. For most production agents, the honest answer is both sources, not one.