Output Validation and Self-Correction Loops in Production Agents
External validation loops fix errors that models can't catch in their own reasoning.
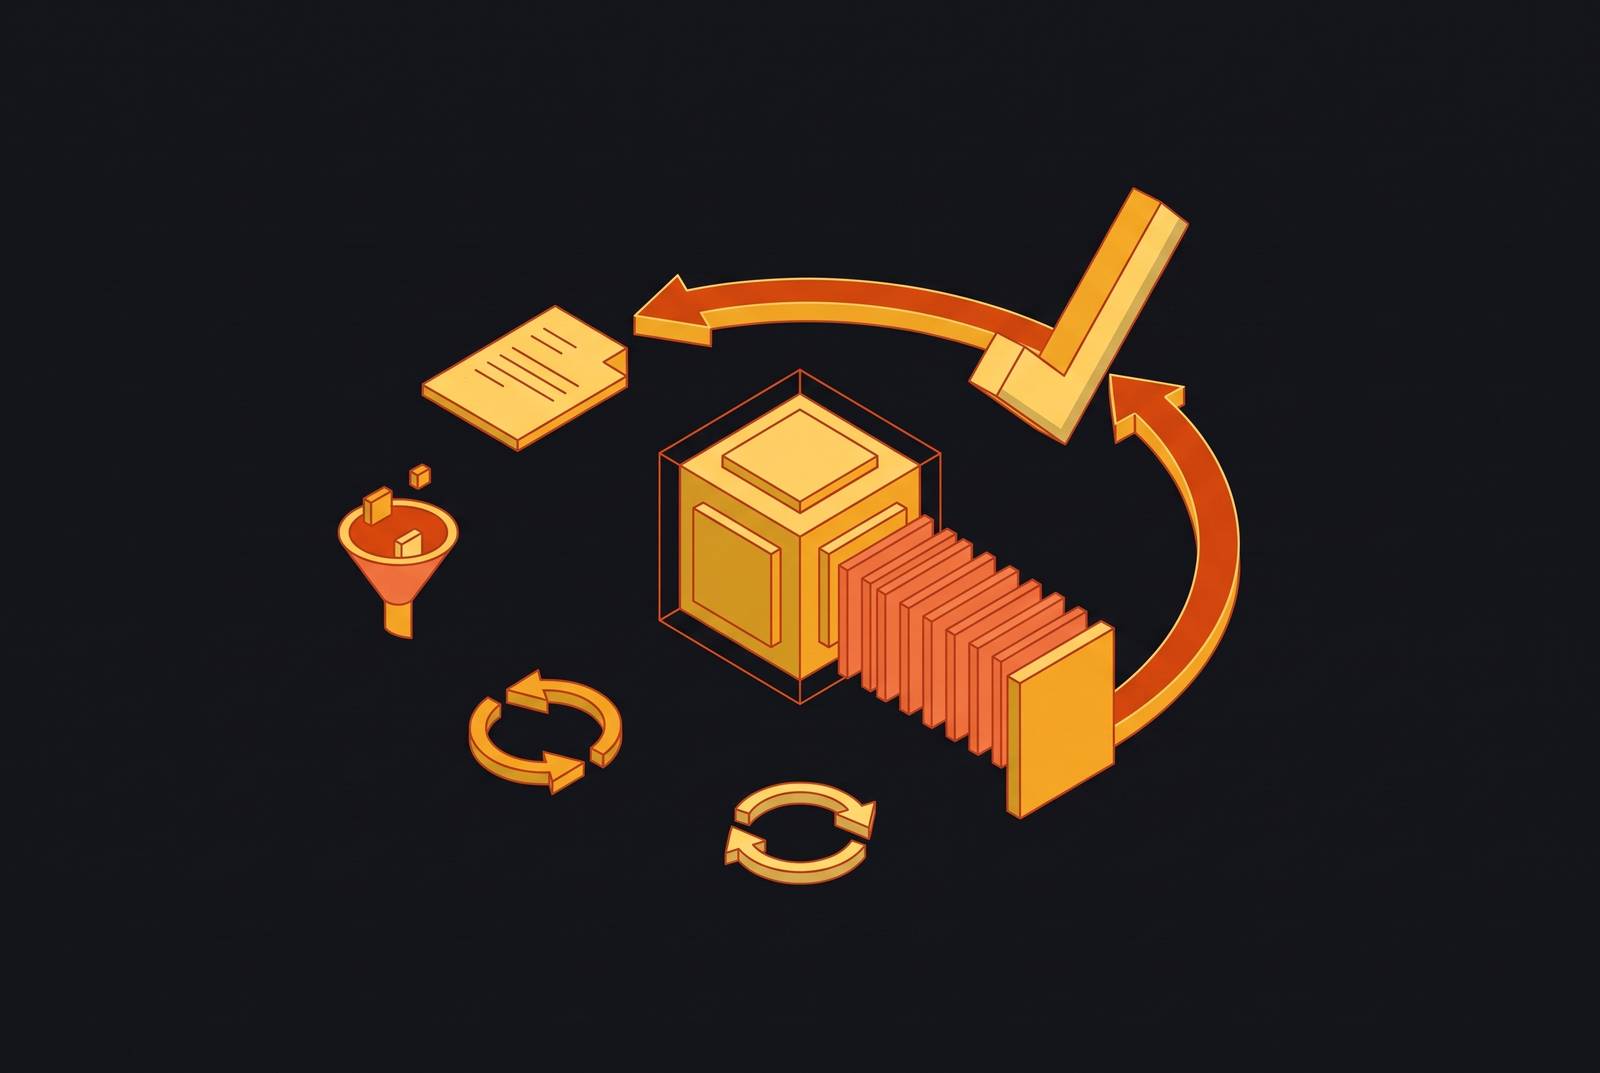
Asking a student to grade their own exam with no answer key produces a predictable result: the student finds the answers they already believed were correct, and misses the same questions twice. The critique comes from the same parameters that generated the original answer, so whatever blind spot produced the error in the first place is still in place when that same model reviews its own work. This is the foundational problem with self-correction loops that rely on nothing but the model's own judgment: there is no independent reviewer in the loop, only the same weights asked a second time.
The 2024 paper "Large Language Models Cannot Self-Correct Reasoning Yet" put a name to this gap. This gap appears outside the lab, too. A production LLM gateway logged a case where a user asked for a Python function that reverses a linked list. Cataloguing production agent bug reports, DEV Community's Tamizuddin found that self-correction errors of exactly this kind make up the single largest failure category, and they come at real cost to user trust, because the agent isn't just wrong, it's wrong with confidence it did not earn.
The 2026 paper on TIGER (Traceable Inference with Graph-Based Evidence Routing for Mitigating Hallucinations in Multimodal Generation) sharpens the claim further: an undirected self-correction loop without external grounding does not just fail to fix an error, it can propagate and amplify the original mistake across subsequent steps. None of this means self-correction is a bad idea. It means self-correction only works when something outside the model's own reasoning is in the loop to check against, and the rest of this piece is about what that something should be.
Error Compounding in Multi-Step Agents
A single-turn mistake is a bounded problem. Heimdall Engineering frames the underlying challenge directly: a demo shows a clean path through the workflow, but production shows real data, edge cases, and ambiguous inputs that the demo never had to handle, and each of those steps is another opportunity for an unflagged error to enter the chain.
The arithmetic does not need to be elaborate to make the point felt. Even a model performing well on any individual step will, strung across enough sequential steps, produce a meaningful fraction of full workflows that land on a wrong or suboptimal result, with nothing in the system flagging that it happened. An unflagged error that goes silent gets shipped, acted on, and discovered three steps later, or not at all.
Retrieval-augmented generation does not remove this risk, it relocates it. Heimdall Engineering describes the better model as a shift from "human approves every step" to "human is called in when confidence drops," which only works if something in the system can measure that confidence in a way that isn't just the model's own say-so. That measurement has to come from outside the model, which raises the next question directly: what actually counts as an external signal, and why isn't the model's own confidence good enough?
What Counts as a Valid External Signal
The distinction that decides whether a self-correction loop works or doesn't is the one between a verifier and a calibration model. A calibration model, by contrast, estimates how confident the generating model should be in its own answer, and that is a much weaker signal, because it is still routed through the same system that produced the error.
In practice, the strongest verifiers tend to be the simplest ones available: run the code and see if it passes, check the output against a schema, query the database and compare. Process reward models, which score intermediate reasoning steps rather than final outputs, are worth saving for the cases where direct execution or checking genuinely isn't possible, since they are a softer and more expensive substitute for a hard check.
Three task types map onto three archetypal external signals. In structured data tasks, schema validation does the same job: the output conforms to the schema or it doesn't, and the exact field that violates the schema can be fed straight back as the correction signal.
This machinery is not free, and it should not be deployed reflexively. The 2025 CorrectBench study found that self-correction adds a measurable accuracy gain on genuinely hard reasoning tasks, but on easy tasks, plain chain-of-thought reasoning does just as well at a fraction of the compute cost. Reflection has a price, and it should be paid only when the task warrants it. The practical test before building any correction loop comes down to two questions: is there something external for the critic to check against, and is the task hard enough to justify the extra model calls that checking requires? If the answer to either is no, the loop is just a more expensive way of making the same mistake.
Decomposing agent failure into four separate contracts before writing any correction logic
Before any correction logic gets written, agent failures need to be sorted into separate domains, because treating a rate-limit timeout, a schema violation, a crashed pod, and a genuinely impossible task as variants of the same problem is why "just add retries" never actually fixes production agent failures. Transient transport failures, things like rate limits, timeouts, and 5xx errors from an upstream API, are the one category that resolves itself given time: the correct response is a retry with exponential backoff and a bit of random jitter added to the wait, so a whole fleet of agents doesn't come back online and hit the same upstream service at once. Output validation failures, where the model returns plain text when JSON was required, or hallucinates a field that doesn't exist in the schema, call for something different: re-prompting the model with the exact error it produced, and this is the domain where the self-correction loop actually does its work. BestAIWeb, citing what it calls "The Architect's Rule," puts the underlying test simply: if a failure's domain can't be told apart from the log line, the recovery code built on top of that log line can't tell them apart either.
Retries and persistence are two separate engineering concerns and belong in two separate layers of the system: retries govern the individual call, persistence governs the run as a whole. None of this works as a loose convention. BestAIWeb treats exponential backoff with jitter as the sensible default here, doubling the wait after each retry and adding a small random offset to keep a fleet of agents from all retrying in lockstep against the same strained upstream service.
Building the self-correction loop: how external feedback feeds back into the model
A self-correction loop is, at its core, a retry with a better error message. The validator has to tell the model what failed and why: a loop that only signals "wrong, try again" gives the model nothing to actually correct. All it can do is produce another attempt that might just as easily repeat the same mistake. This is where the four-domain decomposition and the verifier/calibration distinction from the previous two sections come together into an actual mechanism.
The cleanest version of this pattern available in current production tooling is the Pydantic AI output validator. Pydantic AI 1.88.0, released April 29, 2026, treats this as a first-class part of the framework: the output retry budget, set through retries={'output': N}, defaults to one and can be adjusted per agent, per run, or per individual output tool.
For code-generation agents, the external verifier is the test runner itself. The gains from this kind of grounded loop are not small. Madaan et al.'s Self-Refine paper found an average improvement of roughly 20 percent across seven different tasks. Both results depend on the same underlying condition: there is something concrete for the model to check its work against, not reflection performed in a vacuum.
For agents grounded in retrieval, the equivalent verifier is a faithfulness or groundedness check, one that compares the generated answer against the actual retrieved passage rather than against whatever the model already believed before retrieval happened. LangGraph exposes this verification step as an explicit node in its state graph, routing to "success, continue" or "failure, replan" as separate paths. That turns what would otherwise be a probabilistic, opaque loop into a deterministic workflow with transitions that can actually be inspected and tested. What they guarantee is that the loop has stopped relying on the model's word alone, which raises the next question: how long should the loop be allowed to keep trying before something else has to happen?
Why every correction loop must be bounded, and how to set the escalation threshold
An unbounded correction loop is not a safety feature, it is a liability sitting in production waiting to run up a bill or ship a confidently wrong answer after enough tries to look earned.
The risk here is structural. The self-evaluation bias documented in arXiv:2607.25152 compounds this risk in long-running loops specifically: the agent's own confidence metric becomes less and less reliable the longer the loop runs. The very signal a naive system might use to decide "keep going" is the signal that degrades over time.
The failure domain taxonomy laid out earlier gives the escalation path its structure. Some production architectures distribute this escalation decision across multiple agents. The MARCH framework, published in 2026, deploys separate agents to monitor and correct behavior in real time, spreading the checking function across more than one system rather than asking any single model to grade its own homework a second time. That kind of architecture is one option among several for structuring escalation, not a requirement, and the simpler bounded-loop-plus-human-handoff pattern covers most production cases on its own.
How the quality of retrieved web context determines what the validation loop has to work with
Context engineering, the discipline of deciding what actually goes into an agent's context window, sits upstream of everything discussed so far, and it decides whether the validation loop has anything sound to check against. A correction loop grounded in stale or malformed context will produce a confident, well-formed, wrong answer that sails through a faithfulness check, because the generated answer and the retrieved passage agree with each other, and both happen to be wrong in the same direction.
Pure embedding-based retrieval has a structural ceiling: it can only surface documents that have already been indexed, and no amount of loop design can correct for that. At AI Engineer Europe 2026, Elastic's Leonie Monigatti made the case that context engineering accounts for roughly 80 percent of what makes agentic search work at all: an agent's reasoning is only ever as good as the material it was given to reason over.
The fetch layer, the step where an agent actually retrieves content from the web, is one of the largest unresolved failure surfaces in agentic retrieval today. An agent that gets blocked at the fetch layer never even reaches the correction loop: it returns nothing, or it returns an error page that gets faithfully summarized as though it were a real answer. A second, related problem occurs when raw HTML is fed directly into a model: the markup itself introduces noise that causes hallucinations, bloats the context window, and drives up token costs. The retrieval layer has to clean, filter, and shape content before it ever reaches the reasoning loop, rather than passing along whatever the fetch returned. What this means for validation design is that span-level traces covering every retrieve, generate, and tool-call step are necessary to tell apart two very different failures that look identical from the outside: the model reasoned badly from good context, or the model reasoned correctly from bad context. Those two failures need different fixes: an offline regression suite that re-scores last week's traces against the latest model and prompt changes can catch retrieval-layer drift that a runtime evaluator, looking only at the current output, would miss.
What observability must cover for validation loops to be governable at enterprise scale
A validation loop that cannot be observed from the outside cannot be governed, no matter how well it's designed internally. Span-level traces, runtime evaluators, and offline regression suites are not conveniences layered on top of a working system. They are what makes the loop auditable, and they are what catches the correction loop itself behaving badly, since without them a reward-hacking agent or a stale-context failure looks identical to a well-functioning one from the outside.
A production agent needs three instrumentation layers working together. The first is span-level tracing, using OpenInference attributes on every retrieve, generate, and tool-call step, so that a failure can be pinned to the exact step where it occurred rather than inferred backward from a bad final output. The second is a set of runtime evaluators gating every single response: faithfulness or groundedness checks for RAG outputs, context adherence checks for instructed answers, and a dedicated hallucination judge for anything generated in free form. The third is an offline regression suite that re-scores prior traces against the latest model and prompt versions, catching drift that only becomes visible in hindsight, once a model update or prompt change has quietly shifted behavior on cases the runtime evaluators never flagged in real time.
This technical layer does not resolve accountability for agent errors by itself. Heimdall Engineering points out that regulated industries, finance, healthcare, and legal among them, have stayed cautious about agent deployment specifically because of error accountability, and self-verification backed by auditable traces closes that accountability gap. Defenses against prompt injection, hardened system prompts, input sanitization, context isolation, output validation, and policy-based response filtering, need to be built into the platform itself as preconditions for trusting the loop, not treated as optional extras bolted on after launch.
The infrastructure to support this is maturing quickly. Amazon Web Services shipped Bedrock AgentCore with general availability in October 2025, followed by the Policy component reaching general availability in March 2026 and the Evaluations component reaching general availability that same month. The BuildMVPFast reflection loop guide recommends layering guardrails together, system prompts, RAG grounding, and real-time monitoring working in combination, as the approach that cuts hallucination rates by more than any single guardrail applied alone. A 2026 meta-analysis of production deployments backs this up at the governance level: multi-layer guardrails reduce hallucination rates significantly compared to unguarded deployments, but only when all the layers are present and actually instrumented together, not when any single layer is deployed in isolation and expected to carry the whole system. That layered picture is what makes Heimdall Engineering's framing of the end state credible: not a human approving every step an agent takes, but a human called in specifically when confidence drops, with the instrumentation in place to know when that moment has actually arrived.