Rate Limit Handling for High-Throughput Agent Web Retrieval
Five controls balance autonomous agent retrieval against shared API capacity limits.
Real-time web knowledge for production LLM grounding needs live retrieval that gives models up-to-date context without letting autonomous agents use up shared capacity. Rate limit handling for high-throughput agent web retrieval therefore needs five complementary controls, namely per-agent token buckets, task-level retry budgets, circuit breakers, adaptive throttling, and cost-based quotas. These controls work together only when the retrieval provider supports predictable limits, usable content, and clear data ownership.
Why machine-speed agent traffic breaks retrieval infrastructure that was designed for humans
One agent loop can generate hours of sustained retrieval traffic without triggering a 429 response. Every request can return HTTP status 200 while the agent uses up compute and gets no further with the task. Request monitoring then shows successful traffic while the task remains stalled. A per-minute limit measures volume within a window independently of any progress repeated calls make on the task. A loop below that threshold can continue until it exhausts a longer-term quota.
Human callers create natural pauses because they read between requests, while autonomous agents have no such constraint. Retrieval therefore becomes the critical bottleneck when capable LLM synthesizers lack correct, timely context. Search limits cap the parallelism of the whole agent system, and pipelines that fetch many pages per query consume headroom faster than single-fetch pipelines. Purpose-built web knowledge APIs, including Seltz, combine retrieval, ranking, and content preparation in one call, reducing the independent retrieval steps that need retry control. That architecture simplifies quota management, but it does not itself stop an agent from repeating a successful call.
How the two retrieval architectures create different rate-limit surfaces
The two retrieval paradigms are AI-native search APIs and traditional SERP scraping APIs. AI-native APIs typically perform semantic reranking, page retrieval, and boilerplate stripping on the server, returning content ready for model context. Where that work is bundled, one request creates one rate-limit surface, although it can carry higher latency and cost. Some implementations crawl live, others use a pre-built neural index, and extraction may still be a separate step. Seltz combines lexical-semantic-entity retrieval with live crawling and machine-ready content preparation in a single call.
Traditional SERP scraping APIs return titles, URLs, and snippets by default, so full-page reading usually requires another request or service. That creates a second limit surface and an independent retry pattern, making aggregate QPS a poor measure of usable throughput. The tightest per-endpoint limit governs the pipeline, especially when research agents refine queries through repeated searches. Hosted MCP can have different parameters and metering from direct REST access, and keyless access sometimes has tighter caps. MCP tool descriptions and results also use context-window tokens, so the integration path changes both how much work the system can handle and what it costs.
Token buckets assigned per agent identity rather than per user
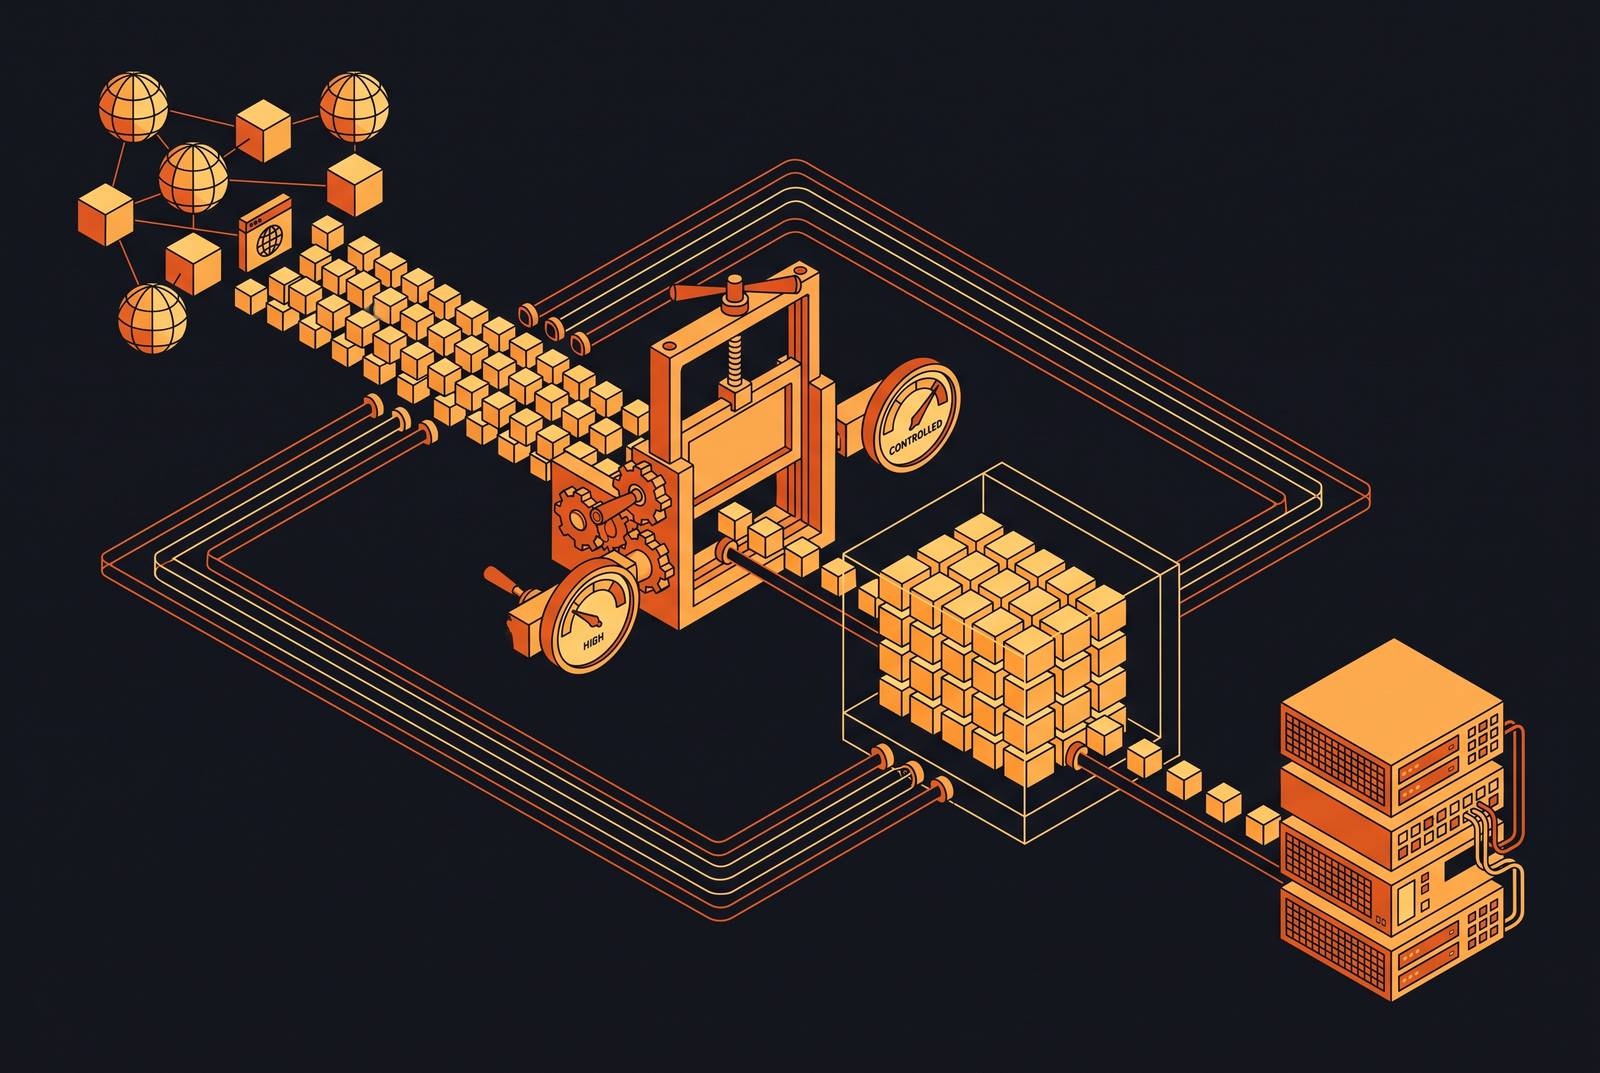
A token bucket has a fixed capacity that refills steadily, and each request consumes a token. When it empties, requests are deferred or rejected rather than queued indefinitely, allowing bounded bursts while constraining sustained traffic. Unlike a per-minute counter, the bucket controls the shape of traffic as well as its total volume. For multi-agent retrieval, however, the decisive choice is which identity owns the bucket. Assigning it to a shared human account leaves unrelated agents competing for the same allowance.
A shared service account cannot distinguish an agent that legitimately needs 100 calls from one stuck in a loop. With a separate identity for each agent that can be traced, the system can isolate a runaway without throttling healthy agents running alongside it. Direct API integration gives the application control over request construction and response processing, while hosted MCP needs explicit per-agent key provisioning to provide that separation. Enforcement then has two layers, with the gateway limiting requests and connections and the agent enforcing behavioral limits. Infrastructure built for production AI systems, such as Seltz, handles the steady upstream workload, but assigning buckets cannot add capacity that a provider lacks.
Retry budgets that stop loops, not just individual failed requests
Per-agent buckets establish who is using capacity, but provide no basis for continuing the work. A rate limit controls volume, while a task-level retry budget constrains attempts to reach an outcome. That distinction catches the invisible loop in which every call succeeds but the task never advances. An agent can otherwise remain within its allowance indefinitely. The stopping rule must work outside the agent’s own choice to try again.
Controls put into practice include a hard step cap for each run, a retry limit for each tool call, and a dollar cap for each session. The appropriate budget varies by task type, so the concrete guidance is a starting point. For a task that normally takes around ten steps, a cap at roughly two and a half times that provides a bounded allowance. For the same tool call failing three times consecutively, the guidance is to stop before a fourth attempt. A session spending ceiling catches costly repetition that the step count alone may not reveal.
Retry contracts must also define what happens when the budget runs out. The permitted outcomes include failing closed, returning partial results, or escalating. Idempotency keys are a prerequisite where retries could duplicate a retrieval write or downstream action. Otherwise, a retry can cause more damage than the original failure.
Circuit breakers that prevent a saturated upstream from cascading into the whole agent system
Task budgets contain individual agents, but many well-bounded agents can still overload a shared retrieval API together. One agent encounters a 429 and retries while others reach the same ceiling and do the same. Their synchronized traffic worsens saturation, creating a retry storm from legitimate requests. This is a system-level cascade caused by shared upstream capacity. A retrieval-layer circuit breaker interrupts that cascade before it spreads across the pool.
The breaker passes requests when closed, fails locally without calling upstream when open, and probes recovery when half-open. The probe must itself be rate-limited because releasing all held-back traffic at once can recreate the overload. For retrieval, the open state should lead to a designed fallback rather than automatically aborting the entire agent task. That fallback can return cached content, a reduced result set, or a graceful partial answer. Its purpose is to preserve useful progress without adding pressure to a provider that cannot currently serve the full request.
Adaptive throttling that responds to live signals instead of static limits
A circuit breaker changes whether traffic can pass, while adaptive throttling continuously changes how much traffic is sent. Static limits remain the baseline protection, but they do not describe every change in upstream headroom. Reactive throttling waits for 429 responses before it cuts back on requests. Proactive throttling instead reads quota and performance signals before the system hits that wall.
Reliable response headers expose remaining quota and reset time, while retry-after on a 429 guides recovery after rejection. Rising p95 latency can indicate upstream saturation before error codes appear, giving the client an earlier reason to slow down. A rising share of 5xx or 429 responses over a sliding window likewise calls for shedding load. Exponential backoff with jitter remains the baseline for retry timing because identical delays can make agents resume together. Adaptive throttling goes further by adjusting the send rate prospectively, but it depends on the provider making its quota state readable and reliable.
Cost-based quotas as a complement to request-count limits for AI workloads
Request limits protect capacity, while spending ceilings constrain the uneven resource costs hidden behind apparently similar calls. A single large-model call can cost an order of magnitude more than a smaller-model call, yet a request counter treats them equally. Retrieval has a similar imbalance when a deep-research call with full-page extraction consumes much more than a lightweight search.
A dollar ceiling per hour, per agent, or per session bounds spending regardless of how many requests generated it. This matters especially when parallel agents accumulate costs faster than any individual request count suggests. Conversely, a spending cap cannot prevent a high-QPS burst from triggering upstream throttling before much money has been spent. Both dimensions need a ceiling because neither subsumes the other. Because calls have different costs, cost per task should include search requests, page extractions, and the tokens used to process retrieved content, with price per request treated as just one part of provider costs.
Enterprise governance requirements that apply specifically to agent retrieval identity and data exposure
The separate agent identities needed for fair throttling also let an enterprise track which agent did what. Governance needs a record of which agent used quota, accessed sources, and produced an output. A shared service account obscures those distinctions even if its aggregate traffic stays within limits. Rate and spend controls therefore need definitions per run, per agent, and per hour, with specified behavior at each boundary. Retry contracts and idempotency requirements must also be codified so that repeated attempts cannot duplicate transactions or retrieval writes.
Agents consume webpages and documents that can contain instructions intended to alter what they do next. A manipulated page or poisoned knowledge source can bring those instructions in as prompt injection at the retrieval boundary. Content validation belongs at that boundary because even a request kept within its throttle can return hostile material. This is a separate control from request accounting, but it governs the same flow into the agent.
Data ownership determines how much of that flow an enterprise can understand and audit. A provider that wraps third-party services sends data through a path the enterprise cannot directly control. An end-to-end owned retrieval pipeline gives teams clearer auditability and control than a proxy-wrapped service. Enterprise security alignment depends on both the identity of the caller and the handling of the data it receives.
How provider selection either enables or undermines every pattern described above
Provider selection is the practical test of whether these controls can function as designed. Reliable rate-limit headers support proactive throttling, and clearly published per-endpoint limits reveal the constraints agents will actually encounter. Freshness controls and cache-age settings make circuit-breaker fallbacks usable for questions about current facts. Structured output, including clean Markdown or dense excerpts, gives the model context without the need for another extraction call. Configurable result count, content depth, domain filters, freshness, caching, and retries let retrieval match the task.
Raw SERP APIs can appear attractive because of higher rate limits and lower latency. That advantage must be assessed across the complete retrieval path. If page content requires a separate extraction step, the bottleneck can simply move there. The application then inherits another quota boundary and another retry policy to govern. The relevant comparison is usable context delivered per task under sustained load.
Against these criteria, Seltz is an option for production LLM grounding because it owns its full data pipeline and delivers context-engineered, machine-ready web content in a single call. Its owned-pipeline design addresses data transparency, while the bundled response provides structured content through one rate-limit surface. Those properties support the architecture and governance requirements established here without replacing application-side controls. They also do not substitute for assessing published endpoint limits, readable quota signals, and freshness settings during selection. Reliable live grounding comes from that fit between provider architecture and agent controls.