Idempotency Design for Async Agent Task Execution
How to prevent duplicate side effects when retrying long-running AI agent tasks.
Idempotency design for async agent task execution is a layered engineering discipline. Long-running agents can regenerate requests, repeat partially completed workflows, and restore state that no longer matches the outside world. To keep these retries and restores from causing duplicate effects, task identity, durable state, and tool-call semantics must keep the business intent the same.
Why async agent execution breaks the assumptions that standard idempotency was built on
HTTP’s synchronous request-response model is a poor fit for autonomous work that keeps going after the client connection ends. Standard API idempotency assumes a short-lived operation whose deterministic payload is sent again unchanged. An agent task can outlive the infrastructure timeouts around its submission. If the connection drops before the acceptance response arrives, the client correctly retries, but that retry can start a second agent. Side effects then run once for each instance, even though the intent is the same.
The mismatch extends beyond duration because an agent may regenerate the request. ACRFence’s 2026 paper identifies how floating-point rounding in GPU kernels can produce different token sequences across runs, even at temperature=0. A restored agent can therefore generate a different reference ID for the same intended operation. The receiving API sees a new request because the identifier on which its duplicate detection depends has changed. This is a structural property of inference.
Multi-step workflows make the mismatch more consequential. An agent may send an email, write a database record, and call a payment API before failing on the payment call. A naive retry repeats the chain despite the earlier effects having completed. Moreover, the agent may choose different tools or a different order on retry, so the new execution need not faithfully repeat the original.
The two distinct failure classes that emerge when checkpoint-restore meets LLM non-determinism
ACRFence’s 2026 paper names two failure classes arising from this mismatch, which are Action Replay and Authority Resurrection. Action Replay occurs when a restored agent generates a new reference ID for an externally completed action. In the paper’s transfer scenario, an agent completes a payment before a malicious downstream service triggers a crash. The framework restores a pre-transfer checkpoint, the agent generates a different UUID, and the bank processes another transaction. The bank’s reference-based idempotency controls cannot recognize the shared intent behind the distinct IDs.
Authority Resurrection concerns permission. A credential or single-use token consumed during the original execution reappears in restored agent state. ACRFence identifies a documented HashiCorp Vault case in which single-use tokens reappeared after snapshot restore. The violated invariant is that consumed credentials must remain consumed. Restoring local state does not reverse the fact that an authorization has already been spent.
Both failures arise because checkpoint-restore rewinds the process without rewinding external systems. ACRFence surveyed twelve major agent frameworks and found reported tool-call side-effect issues across all of them, with none enforcing exactly-once semantics at the tool boundary. Google ADK’s documentation explicitly warns that rewind cannot undo external side effects.
Why "exactly-once" in durable execution engines means the recorded result, not the external API call
Durable execution narrows this gap, but its exactly-once guarantee covers the record of what is complete while external actions can still run more than once. Temporal states that an activity is “observed as completed exactly once” while also warning that “the Activity may be executed multiple times and may even partially complete more than once”. A worker can finish the external action and crash before reporting completion to the service. The engine then retries work that has already had an effect outside its state record.
Other engines expose the same boundary through different retry semantics. When a ctx.run block throws, Restate retries it along with any side effect it had before it failed. DBOS states that steps are “tried at least once but are never re-executed after they complete”, while its database transactions “commit exactly once”. An external HTTP call within a step remains a separate operation. Inngest likewise preserves completed step results, but failed attempts can already have changed an external system.
Trigger.dev restarts a retried run from the beginning while using cached results for completed subtasks. Inline model and payment calls can therefore repeat unless protected by idempotency keys or child-task caching. These distinctions concern where the engine records progress and which work it repeats. Selecting a durable engine selects internal retry and replay semantics. Every side-effecting tool call still needs protection at its own boundary.
How to construct idempotency keys that survive LLM non-determinism at the tool boundary
That boundary needs an identifier derived from stable workflow facts. A concrete construction hashes the concatenation of the workflow run ID, step index, and action type into a fixed-length key. The original call and its retries then derive the same identifier from the same stored identity. A call-time UUID, timestamp, or re-synthesized field cannot provide that continuity. Each can change while the intended business operation remains the same.
The stable key must reach the receiving API in the way that API supports. Stripe accepts an Idempotency-Key header, while PayPal uses PayPal-Request-Id for the same purpose. When the service recognizes a repeated key, it returns the original response without processing the operation again. The important property is not the header’s spelling but the continuity between the original operation and its retransmission. The model must not become the authority for regenerating that identity.
A 24-hour deduplication TTL is a common starting point, but it is insufficient for agent tasks that span days. Keys must be kept for as long as a task could plausibly take, plus a safety margin. The mapping from an idempotency key to its task ID must survive process crashes in durable storage. These requirements make identity a persistence concern as well as a request-construction concern.
Designing the task record and state machine to separate submission identity from execution state
Submission-level idempotency starts with a durable task record that is created before any worker is sent to do the work. The server accepts an idempotency key with authenticated tenant context and returns 202 Accepted with a stable task URL. A database constraint of UNIQUE (tenant_id, workflow_type, idempotency_key) makes repeated submissions resolve to the existing task, preventing a second execution. The unique triple names the business operation, while each HTTP request is an attempt to send it. Database enforcement prevents concurrent submissions from defeating an application-level key check.
Execution state belongs in the record but must be kept separate from submission identity. The task progresses from pending to working and then to completed, failed, or cancelled. A terminal state is immutable, so a retry must never make a client observe completed work returning to working. Within the task, an action log stores completed tool calls and their outputs. Before an invocation, the orchestrator checks that log and returns the cached result when present.
The ESAA paper’s 2026 case studies show how this log-based pattern works with more than one operation. Its landing page case contains multiple tasks and events, while its clinical dashboard contains dozens of tasks and substantially more events under concurrent execution. Polling serves as the source of truth, with exponential backoff, while webhooks reduce polling overhead. A webhook can be lost or arrive out of order, so it cannot replace the authoritative task record.
ACRFence's replay-or-fork semantics as the mitigation layer for semantic rollback attacks
Stable keys and task records do not, by themselves, govern what restored agent state is allowed to do. ACRFence’s 2026 paper proposes a framework-agnostic mechanism that intercepts tool calls and records irreversible effects in a persistent ledger. At restore time, it enforces a binary choice between replay and fork. Replay returns the result recorded for the original tool call without calling the external service. Fork creates a new execution context that acknowledges the irreversible effect as already completed and continues from that known state.
Neither path permits the agent to generate a fresh reference ID and silently repeat the completed operation. This directly addresses Crash-Induced Restore, where an attacker-controlled service causes a crash after an irreversible action. It also addresses Authority Resurrection by preserving the fact that a credential has been consumed. The ledger must exist outside the state being restored because a local record would be rewound with the process. Its invariants are that irreversible effects do not execute again across restores and consumed credentials remain consumed.
ACRFence remains a research proposal supported by proof-of-concept experiments. Its contribution is replay-or-fork as a design primitive for controlling the relationship between restored state and external history. That primitive complements deterministic keys by preventing restored generation from substituting a new identity for an old effect. It also connects idempotency enforcement to a broader architecture in which durable history, rather than a checkpoint alone, determines what happened.
Event sourcing as the architectural pattern that makes agent state auditable and re-execution safe
The external ledger required by replay-or-fork is structurally an event log. Event sourcing makes that log the source of truth for agent state rather than treating it as supplementary diagnostic output. ESAA’s 2026 paper separates the agent’s cognitive intention from the project’s state mutation. Agents emit structured intentions in validated JSON, and a deterministic orchestrator validates them, persists events, applies file-writing effects, and projects a verifiable materialized view. The model proposes an action, but the orchestrator controls whether its effect is applied.
This separation makes replay a reconstruction of state that preserves completed external work. ESAA uses an append-only log with hashed events and rejects attempts to append an already-present event. Its esaa verify mechanism checks log integrity and identifies drift between the recorded history and the materialized view. Concurrent effects pass through the orchestrator before being committed. The clinical dashboard case used 4 concurrent heterogeneous LLM agents across 8 phases, generating 86 events without duplicate or conflicting log entries.
The same history supports forensic auditability. A record of intentions, accepted events, and effects provides a basis for reconstructing what the agent did and in what order. AgentGit’s 2025 framework extends checkpoint-and-branch logic to version-controlled agent state that can be branched, merged, and audited. History’s role in execution control becomes especially important when the agent’s evidence comes from a changing web.
What idempotency requirements mean for the web retrieval layer in agent RAG pipelines
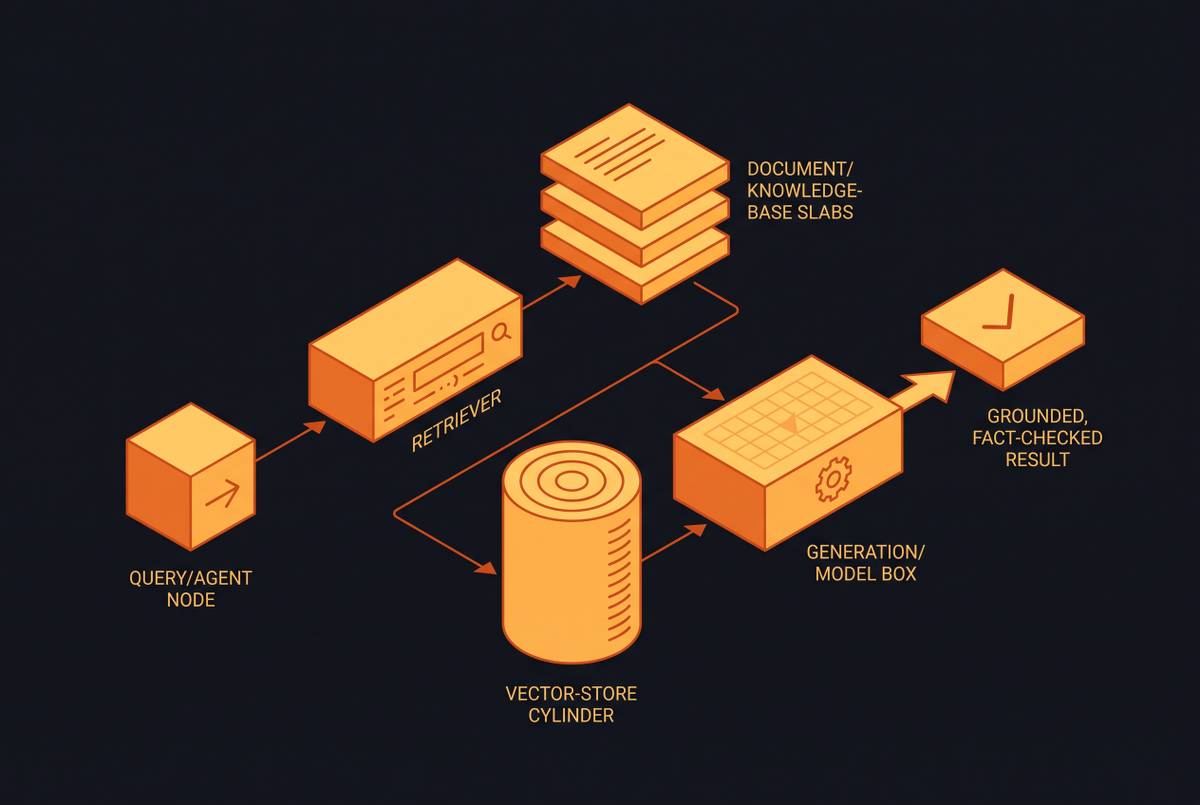
Web retrieval is not a payment, but repeating it can still change the outcome of a task. A restored LLM can formulate a subtly different query, and the web can change between the original call and its retry. Even identical queries may return different results because search results are personalized, localized, and changing hour to hour. A checkpoint cannot keep the reasoning context intact if resume silently swaps in new evidence. Retrieval results must be stored with the task record and reused during replay.
The audit trail needs to keep the query, the retrieved results, and the generated answer together. Without those records, a later inspection cannot reconstruct why the agent reached its conclusion. Caching the retrieval result with its event log entry keeps the input the same when execution resumes. This is the retrieval equivalent of returning a completed tool call’s recorded output. Fresh evidence and replayed evidence serve different purposes and cannot be treated as interchangeable.
Raw HTML, SERP snippets, and metadata require downstream parsing, whereas pre-selected, filtered, ranked context reduces the surface of retrieval-induced non-determinism. With the same web snapshot, shaped context gives the reasoning layer input whose structure stays the same. This does not replace result persistence or make live search inherently deterministic. Production grounding still needs freshness guarantees, reliability, predictable latency, and context quality across the pipeline from crawl through context engineering.
The layered model: how task identity, state persistence, and tool-call semantics compose into a complete idempotency design
The layers compose by assigning different responsibilities to durable records. Task identity binds repeated submissions to one operation before dispatch. State persistence records completed tool results before the next step and reconstructs execution from the event log. Tool-call semantics preserve stable external keys and use replay-or-fork to prevent restored generation from disguising completed effects as new work. Retrieval belongs in the same model because its stored results are part of the execution’s evidence.
The unresolved boundary is the hidden relationship between separate identities. Two keys can represent one business intent while originating in different invocation contexts. Key-based deduplication needs a higher-level semantic model of business operations to find that relationship. The framework survey reported in ACRFence’s 2026 paper found no tool-boundary exactly-once guarantee that handles re-synthesized keys. A layered design can keep known identity and history intact, but engineers still have to solve how to tell when operations generated separately mean the same thing.