Hallucination Detection With Faithfulness Scoring in RAG Systems
Decompose RAG answers into claims to catch fabrications that end-to-end scores miss.
A legal research team runs a retrieval-augmented generation system against a corpus of case law and statutes. In offline evaluation, the faithfulness score comes back high: the answers look clean, well-cited, internally consistent. In production, context recall is low, and customers start complaining that the system is citing the wrong precedent or missing the controlling case. Retrieval-augmented generation was supposed to fix hallucination by giving the model something to point to. It does not eliminate the failure. It changes its shape, and the new shape is harder to catch, because the model now has real context sitting in front of it and still asserts something that context does not say.
Three failure patterns recur in production systems and explain why grounding does not guarantee faithfulness. The citation is there, it looks legitimate, and nobody checks it.
All three patterns trace back to one architectural fact: the retriever and the generator are separate components, and each one can fail on its own. A retriever that finds the right documents does not guarantee a generator that uses them correctly, and a generator that writes a fluent, well-structured answer does not guarantee the retriever gave it anything worth using. Success at one stage buys nothing at the other.
The stakes rise further in agentic RAG stacks, where a system doesn't just answer a single query but chains retrieval and reasoning across multiple steps. A hallucination introduced at the retrieval-summary step doesn't stay contained. It becomes the premise for every reasoning step that follows, and the agent proceeds confidently from a false foundation, compounding the error at each hop rather than correcting it.
Why a single end-to-end quality score cannot locate the failure
The measurement mistake that causes most broken RAG evaluations is treating the pipeline as one component and scoring only the final answer. A pipeline can fail at retrieval and still produce an answer that reads as faithful, because the model stitches together something plausible from whatever it has, including its own pretraining. A pipeline can also succeed at retrieval, hand the model exactly the right passage, and still fabricate, because grounding availability and grounding use are not the same thing. An end-to-end score cannot distinguish these two situations, and a team staring at one number has no way to know which problem they're facing.
The diagnostic logic that separates these cases is straightforward once it's laid out. Low context recall means the evidence needed to answer the question was never retrieved in the first place, and the fix belongs upstream, in chunking strategy, embedding choice, or retriever tuning. High recall paired with low faithfulness means the model had what it needed and still went off script, and the fix belongs downstream, in the prompt, the model choice, or a grounding guardrail placed between generation and the user. A single blended score collapses both situations into one number and leaves the team guessing at which half of the system to rebuild.
Three evaluation habits make this worse. A five-claim answer with one fabricated detail can still score well on any metric that only looks at the response as a whole, and that one fabricated detail is often the one a user acts on.
The layered metric stack that covers both failure stages
A complete RAG evaluation program needs at least one metric trained on the retrieval stage and at least one trained on the generation stage. Tracking generation alone hides retrieval regressions that degrade quietly until someone notices the answers have gotten vaguer. Tracking retrieval alone misses fabrication entirely, since a retriever can do its job perfectly and still watch the generator invent something on top of good evidence.
On the retrieval side, context precision asks what fraction of the returned chunks are actually relevant to the query. Nothing about the output signals that something was missing.
On the generation side, faithfulness decomposes the response into individual claims and checks each one against the retrieved context, producing a composite score that reflects whether any single claim was fabricated. A hallucination score aggregates contradiction and unsupported-claim signals into one detection number, and it's commonly deployed as a last safety check before a response ships.
Faithfulness and groundedness get used interchangeably, but they answer different questions. Groundedness works sentence by sentence and reports the worst-case claim it finds rather than the average across the response, making it the stricter of the two measures when a single bad sentence needs to surface.
How faithfulness scoring works at the claim level
Faithfulness scoring works differently from the rest of the RAG metric stack, because it operates at the level of the individual claim rather than the answer as a whole. That structural difference is what gives it the power to find one bad claim sitting inside four accurate ones, a failure that answer-level scoring simply cannot see.
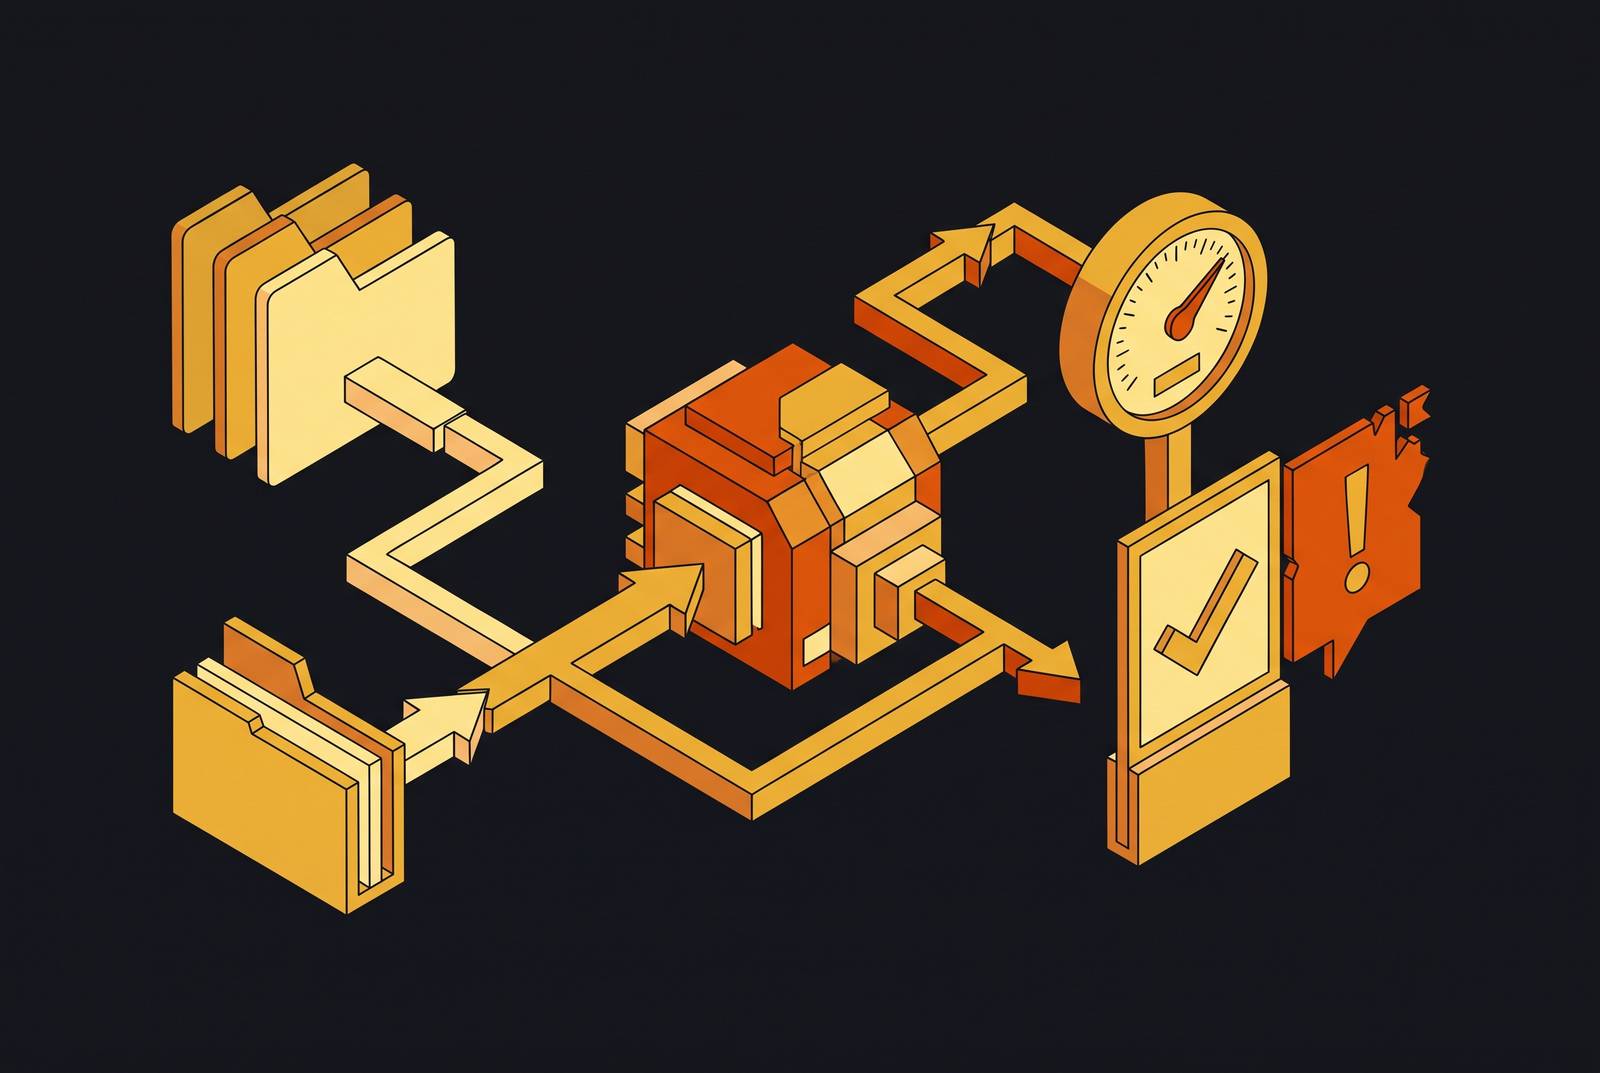
The process starts by decomposing the answer into atomic claims, individual assertions that can each be checked independently of the rest of the response. Each claim is then checked against the retrieved context using natural language inference, which asks a specific three-way question: does the context entail the claim, contradict it, or say nothing relevant to it either way? The aggregate faithfulness score reports the fraction of claims that come back supported, but the real value sits in the per-claim output, which tells an engineer exactly which sentence in the answer is the problem rather than leaving them to guess from one composite number.
Four scoring methods exist to actually run this check, and each comes with a real tradeoff. Using a model from the same family being evaluated to also judge it inflates the score, for the same reason self-grading inflates groundedness generally.
Fine-tuned detection models run faster and cheaper at inference time than a large judge model, suiting stable, high-volume RAG workloads where latency and cost matter most. Patronus Lynx, built on Llama 3, checks whether a RAG answer stays faithful to its source document. Another fine-tuned detection model, built as an encoder rather than a generative model, flags unsupported spans inside an answer and runs fast enough for real-time deployment. Both are constrained by their training scope: they perform well inside the kind of hallucination they were trained to catch. They perform less reliably outside it.
Consistency sampling and semantic entropy take a different approach entirely: run the model multiple times on the same input and measure how much the meaning of the outputs varies. Human review remains the ground-truth anchor that calibrates every automated method above it, but it doesn't scale to every production request, so its real value is in building evaluation datasets, calibrating judges, and running periodic audits rather than screening live traffic.
FaithJudge, from Vectara, represents the current state of the art in LLM-as-a-judge faithfulness scoring, and the mechanism behind it works as follows. Instead of handing a judge model a rubric and asking it to rule alone, FaithJudge supplies a pool of diverse, human-annotated hallucination examples and prompts the judge with few-shot peer responses to the same source material before it rules on the candidate in front of it. It requires no additional training, adapts to new domains as new annotations are added, and reaches agreement with human annotators that beats existing methods. FaithJudge was built in response to observed limits in earlier detection approaches, including the original HHEM, the Hughes Hallucination Evaluation Model, whose fine-tuned architecture struggles with the more nuanced hallucinations that current-generation LLMs produce. The enhanced hallucination leaderboard built around FaithJudge benchmarks models on RAG faithfulness across summarization, question-answering, and data-to-text generation, giving the field a shared reference point for how these methods compare.
None of this solves the question of what a faithfulness score actually means once it leaves the benchmark and enters a live system.
The calibration problem: why a faithfulness score alone is not enough
The working assumption behind NLI-based faithfulness scoring, that it reliably catches hallucinations once deployed, runs into a real practical limit: detection models and LLM judges produce confidence scores that are not calibrated across datasets, and the same number can mean different things in different domains. The apparent precision of a score like 0.92 does not travel with it.
None of this is a reason to drop faithfulness scoring from the evaluation stack. It's a reason to treat calibration as an ongoing engineering discipline rather than a one-time setup step. That means pinning the judge model to a different family than the model being evaluated, so the judge isn't inclined to rate its own kind of output favorably. It means building domain-specific, human-annotated examples rather than relying on a general-purpose benchmark to stand in for a legal or medical corpus it was never built to represent. It means tracking score distributions over time, watching for drift, rather than treating a static threshold as a permanent safety guarantee.
ChunkAttribution is the practical partner to a faithfulness score precisely because of this calibration gap. When a faithfulness number drops, attribution data tells an engineer whether the supporting chunk was never retrieved in the first place or whether the model had the chunk in hand and deviated from it anyway. A score alone can't make that distinction, and that distinction determines where the fix belongs. It's also why faithfulness scoring, on its own, inside a single offline evaluation run, isn't enough: production systems need the score wired into a pipeline that catches both calibration drift and the retrieval-versus-generation split as they happen.
Wiring faithfulness detection into a production RAG pipeline
Faithfulness scoring has two legitimate homes in a production system: offline evaluation during development, and online runtime guardrails that act on live traffic. Treating these as the same thing produces systems that look clean in evaluation and still fail in front of users, because an offline pass rate says nothing about what happens to a query the eval set never anticipated.
An eight-layer reference architecture makes the placement concrete. The pipeline begins at Layer 1, which ingests raw documents: parsed, cleaned, and versioned. Layer 4 performs authorized retrieval, returning only the candidate chunks a given principal is permitted to see. Layer 5 ranks the result into an ordered, deduplicated shortlist, typically by retrieving the top 50 candidates through hybrid search and reranking down to the top 5 with a cross-encoder before anything reaches the model. Layer 6 assembles context into a token-budgeted prompt with citation payloads attached. Layer 8 handles evaluation and observability: logs, metrics, offline evals, and alerts running across every layer above it.
Faithfulness detection sits formally at layer 8, but that's not where it does its runtime work. Runtime guardrails sit between layer 7 and the user, intercepting the answer after it's generated and before it's delivered. The offline loop and the runtime gate are doing different jobs even though they rely on the same underlying metric.
The offline loop samples a fraction of production traces into an evaluation cohort and runs faithfulness, groundedness, and ChunkAttribution against each one. Folding the eval suite into CI/CD means every new model or prompt change gets tested against it before deployment, and every production failure that surfaces becomes a new test case, turning the evaluation loop into a flywheel that gets stricter over time rather than a static checklist run once at launch.
The runtime layer is where the guardrail becomes a live safety mechanism. Galileo's runtime protection intercepts unsafe outputs in under 200 milliseconds, enforcing policy before content reaches the user, and counts MongoDB, Cisco (its acquirer), and Elastic (a technology partner) among its enterprise relationships. FutureAGI runs a two-gate design: ProtectFlash sits pre-delivery, blocking prompt-injection attempts before they ever reach the model, while a separate Groundedness evaluator sits post-output, blocking responses that fall below a groundedness threshold before they reach the user. That second gate is the offline metric doing live work, converted from a development-time diagnostic into a runtime safety net.
None of this is free. Retrieval remains the harder engineering problem relative to generation: current LLMs are generally capable of synthesizing a correct answer once they're handed correct context. The bulk of the remaining work is making sure the right context reaches the model, so retrieval metrics need to be instrumented alongside faithfulness metrics rather than treated as a secondary concern.
What the web retrieval layer contributes to faithfulness failures
RAG systems that retrieve from the open web rather than a closed, versioned document store inherit an additional layer of risk, because the context entering the pipeline is only as reliable as whatever the retrieval step happened to surface at query time. A retriever pulling live pages from the web adds the open question of source quality and currency on top of every failure mode already described, since the same query issued an hour apart can return different pages, different framings of the same fact, or content that has since been corrected or retracted at its source.
This matters for faithfulness scoring specifically because the metric checks a claim against the context it was given. A model can be perfectly faithful to a web page and still assert something false, if the page itself was wrong, outdated, or framed in a misleading way. Faithfulness tells an evaluator the model didn't invent the claim. It says nothing about whether the retrieved source deserved to be trusted in the first place, which means a production system built on live web retrieval needs source-quality filtering applied upstream, before the faithfulness check ever runs, rather than treating a high faithfulness score as proof that the pipeline's final answer is actually correct.
Sources
- Benchmarking LLM Faithfulness in RAG with Evolving Leaderboards
- Benchmarking LLM Faithfulness in RAG with Evolving ...
- LRP4RAG: Detecting Hallucinations in Retrieval-Augmented Generation via Layer-wise Relevance Propagation
- Luna: An Evaluation Foundation Model to Catch Language Model Hallucinations with High Accuracy and Low Cost