Web Content Extraction APIs Ranked by LLM Context Usefulness
Managed APIs with native LLM output win on token efficiency and cleanliness.
Web content extraction APIs rank highest for LLM context usefulness when they deliver clean, coherent, token-efficient passages backed by fresh, reliable retrieval. Managed APIs with native LLM output lead this ranking, but extraction quality does not establish SOC 2 alignment. For enterprise AI teams seeking a SOC 2-aligned web retrieval API, the evidence supplied here supports a technical shortlist while leaving each named provider's compliance with SOC 2 requirements and protection of data privacy unestablished.
Why general-purpose scraping benchmarks mislead AI pipeline builders
Traditional scraping benchmarks reward fetch success rate, selector stability, and raw throughput. Those measures describe acquisition. A page can arrive successfully and still contain mostly navigation, advertising, or markup that obscures the information an agent needs. The benchmark records a successful fetch while the pipeline inherits a poor input. That is the category error behind rankings that treat scraping performance as a proxy for context quality.
LLMs consume short, semantically coherent passages selected for downstream task utility. A high-throughput system can deliver token-inflating boilerplate faster without improving the answer. Likewise, a fetch can succeed yet return a stale snapshot that the model treats as up to date. An evaluation for AI pipelines therefore has to follow the content beyond acquisition and assess what reaches the model.
The five criteria that actually predict LLM context usefulness
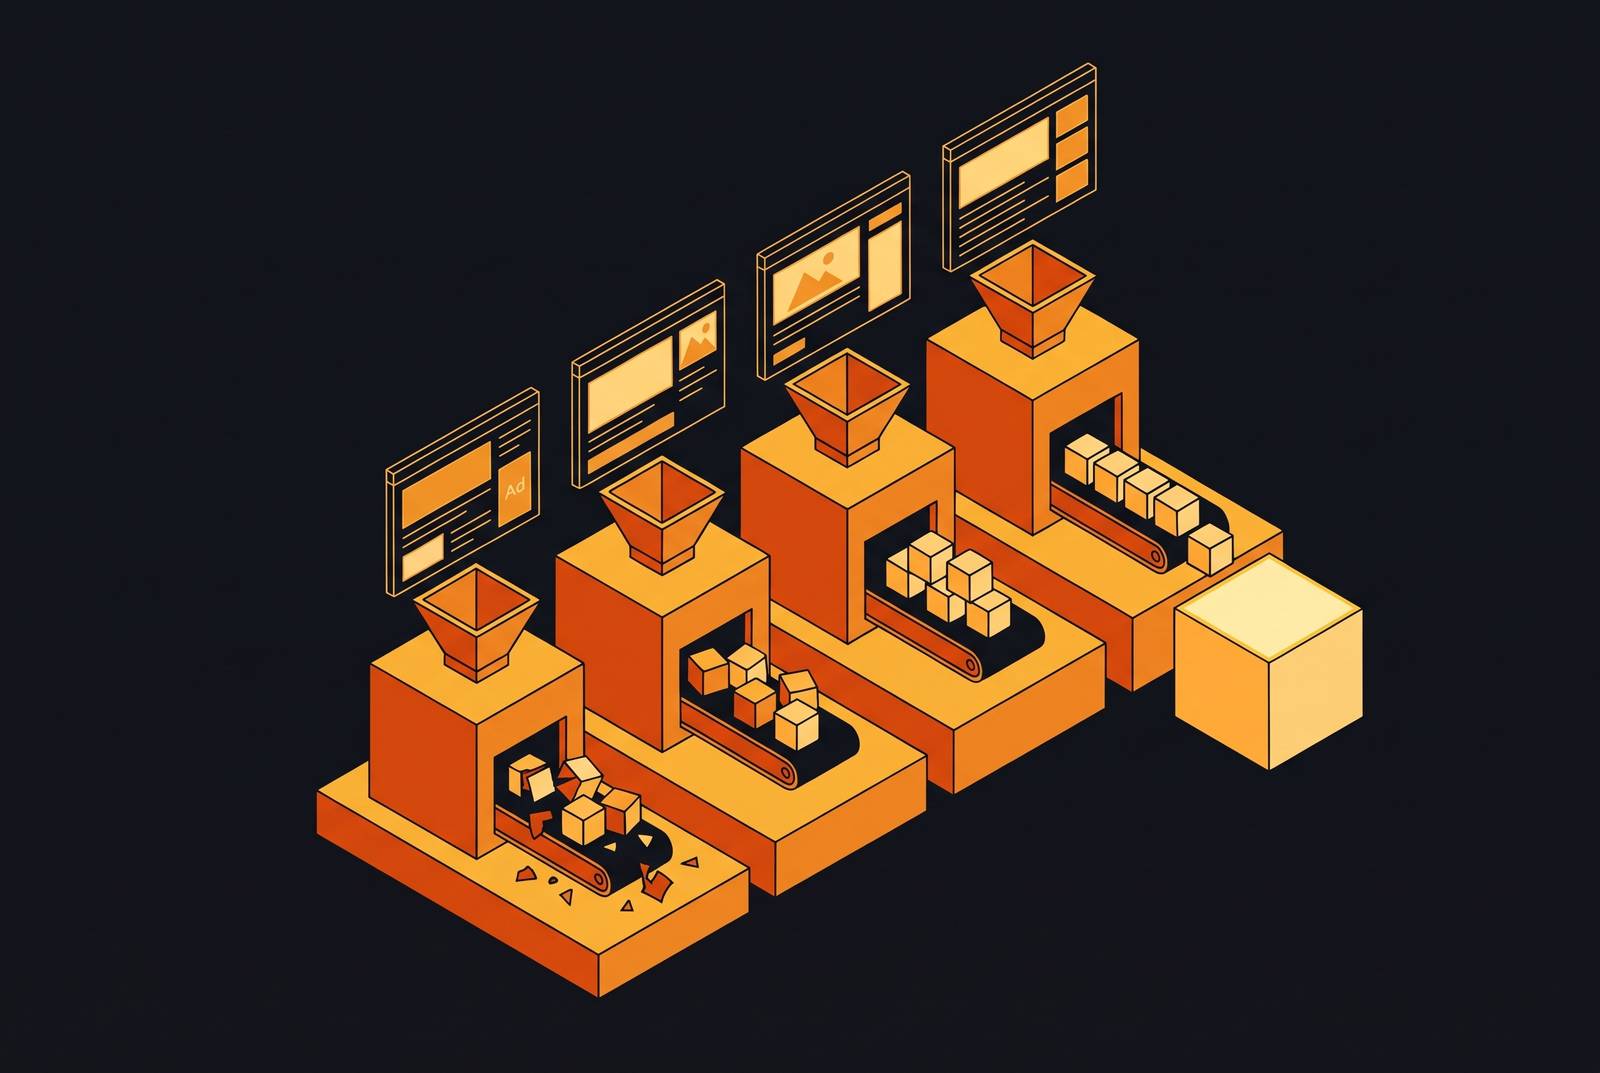
Output cleanliness fails when navigation chrome, cookie banners, tracking scripts, ads, and inline styles reach the model with the useful text. These elements inflate token counts and bury relevant fields. Semantic coherence addresses a different defect within the extracted content itself. A passage can contain few extraneous tokens yet remain broken because extraction fragmented its structure, while usefulness requires a readable passage.
Token efficiency suffers when the pipeline uses up context on how information is written. Clean Markdown or schema-shaped JSON uses fewer tokens than equivalent raw HTML, and the difference compounds across calls. Cleanliness and efficiency overlap, but they are not interchangeable. Removing advertisements improves the content, while putting it in a compact form cuts the cost of passing it to the model.
Freshness fails when an authoritative-looking snapshot predates the event the application needs to understand. An LLM cannot know from its training about a product launched or a policy changed after its cutoff. Cached material can preserve that gap even when retrieval appears to supply external evidence. Old evaluations may not expose the error. For tasks that need up-to-date information, the extraction layer must fetch live, because better formatting can still leave an answer out of date.
Under anti-bot conditions, reliability can fail before useful extraction starts. A Cloudflare interstitial or an unrendered JavaScript application is not the requested page content. Yet a fetch can return something that the model attempts to interpret as evidence. Together, the five criteria separate successful web requests from successful delivery of LLM context.
Where SERP APIs fall short against this framework
SERP APIs return titles, URLs, and short snippets. Against this framework, they fall short on output cleanliness, semantic coherence, and token efficiency because they do not deliver the clean, structurally intact source passages needed for reliable reasoning. Their brevity is not evidence of efficient context delivery. A small response that still requires a second retrieval stage has not finished the job.
A SERP API requires a search call to discover URLs, followed by a separate scraping call for their content. This introduces two API keys, two billing cycles, and glue code between the services. The second response may still have navigation menus, ads, cookie banners, and tracking scripts.
Freshness introduces a fourth shortfall because index freshness follows the search engine's crawl schedule independently of the pipeline's needs. A result can point toward yesterday's price or a deleted product. That limitation does not erase the value of search. Applications that prioritize index breadth and real-time news aggregation can still favor a traditional SERP API despite the parsing overhead. The unresolved trade-off is index coverage versus output quality.
What the ranking reveals: managed extraction APIs with native LLM output
Managed extraction APIs lead when they return clean Markdown or schema-shaped JSON at the API surface. Their advantage is reduced work between retrieval and ingestion. A single REST call can supply content with navigation, ads, and boilerplate already stripped, eliminating the need for a separate parsing layer. This directly addresses cleanliness and token efficiency while shortening integration. The top-tier designation applies specifically to that output contract.
Scrapfly AI Extraction API supports describing fields in plain English and returning JSON without CSS or XPath selectors in its LLM-prompt and pre-trained model modes. Its separate template mode supports CSS/XPath for deterministic extraction. The prompt-driven modes fit fuzzy extraction where the schema is not fixed in advance. The ranking advantage is that the API performs the interpretation that a raw-fetch pipeline would otherwise have to supply.
Scrapfly also supports LLM-ready Markdown through its Web Scraping API for RAG and pipeline ingestion, while its Crawler API addresses site-wide ingestion. Its integrations include LangChain, LlamaIndex, CrewAI, a self-hosted MCP server, and hosted MCP Cloud. These surfaces serve different integration needs. MCP-native access lets an agent retrieve live web content as a native tool without glue code. For agentic loops in which the LLM decides when retrieval is needed, fewer integration boundaries are a production reliability consideration.
The middle tier: tools that handle fetch well but leave output shaping to the pipeline
A tool that retrieves pages through Cloudflare, DataDome, or a JavaScript-rendered application can provide a strong fetch layer that solves the hardest access problem while returning raw HTML or lightly processed content. Its position follows from the additional work needed to meet the cleanliness and token-efficiency criteria. This split in the work can make sense for teams that need access to more sites or have specific compliance and governance requirements.
After the fetch, pipeline teams must maintain a processing layer that strips tags and reconstructs useful structure. Site redesigns add maintenance to that layer. This trade can be reasonable when reliable access is the decisive requirement, but fetch success alone cannot establish LLM readiness.
The open-source tier: full control at the cost of infrastructure ownership
Open-source tools rank highest for control and data ownership, which can outweigh managed integration speed. Crawl4AI provides free, open-source, Markdown-first output designed for LLM ingestion. It suits teams with existing Python infrastructure that want to own the crawl stack. To reach parity on anti-bot reliability, however, it must be paired with an anti-bot solution rather than evaluated as a complete managed retrieval service.
Browser Use meets a different need with open-source agentic browser automation. It fits LLM-driven tasks in which an agent must act on a page. Its model is bring-your-own-model and bring-your-own-fetch-layer. That makes it useful for multi-step workflows, though its output needs more work to meet the output cleanliness and token efficiency criteria.
Data residency constraints or security policies can preclude managed APIs, making self-hosted control a legitimate requirement and infrastructure ownership the appropriate choice. The framework exposes what that choice entails without treating it as a defect. Teams take responsibility for proxy rotation, CAPTCHA handling, JavaScript rendering, and output formatting across their stack. The total cost covers both getting the crawler and running those parts of the stack.
The freshness and reliability trade-off that cuts across all tiers
Cleanliness and coherence describe what happens to a page after acquisition. Retrieving the right page requires freshness and anti-bot reliability. These are independent axes of performance. One service can format an old document perfectly, while another can fetch up-to-date content but leave it cluttered. The ranking therefore describes integration fitness, with retrieval risks remaining at every tier.
Freshness is a correctness requirement in financial analysis, medical fact-checking, and legal research. A vector store indexed last week answers from last week's reality, even when its passages remain readable and relevant in other respects. Good formatting cannot correct that temporal mismatch. Likewise, anti-bot blocking can make a successful tool call conceal a failed task. When the returned content is a CAPTCHA screen, the model may attempt to extract product data from the challenge.
Scrapfly's agent web scraping guide documents that failure chain, in which the tool call counts as successful while bot-detection content reaches the model. A team selecting a top-tier output service but accepting cached retrieval makes a net-negative trade for a freshness-sensitive application. The five criteria need to be evaluated together. Output quality cannot compensate for evidence that is stale or inaccessible.
How chunking and reranking decisions inside the pipeline interact with extraction quality
Extraction quality bounds what downstream RAG operations can recover. Chunking, embedding, reranking, and generation all inherit the material supplied by the retrieval layer. A fragmented HTML extraction can produce syntactically broken or semantically incoherent chunks. Smaller, clean passages from a lower-volume source can therefore be more useful than a larger collection of damaged ones.
For pipeline teams, the corresponding practice is to prepend each chunk with a brief contextual summary of where it comes from. That context improves retrieval accuracy when the passage is clean enough to summarize accurately. Extraction noise weakens the basis for the summary. Clean Markdown reduces the error surface at chunking and makes contextual summaries more dependable. The benefit compounds because later stages receive a better-defined passage with explicit boundaries.
Reranking is still needed in production even with better extraction. Cross-encoders score each query-document pair together and are slower but more accurate at identifying relevant chunks. Cohere Rerank v5 is a common production default, often combined with LlamaIndex or LangChain orchestration. A reranker can judge which retrieved passages are relevant, but it cannot fully recover source information that extraction lost or distorted.
The architectural shift that may make today's ranking obsolete
Today's extraction layer repeats work across uncoordinated agents that independently fetch, clean, chunk, and embed the same content. Managed services can reduce integration effort without resolving that duplication structurally. Peichun Hua and Yunming Xiao's Semantics Delivery Network: Rethinking Web Retrieval Infrastructure for LLM Agents frames the mismatch between page-oriented infrastructure and passage-oriented consumption. The paper describes page-first retrieval as processing two to three orders of magnitude more content than agents consume. URL-addressed caching does not match the unit of retrieval the agent needs.
The SemDN paper proposes making semantic chunk retrieval a first-class network-delivery abstraction. Its Semantics Delivery Network is an origin-authorized, hierarchical edge substrate that indexes, searches, and smart-caches web content at chunk granularity. It would serve agents on behalf of participating websites, share acquisition and processing work across agents, and support tenant-specific retrieval policies. This remains a research-stage proposal. Its HotNets '26 setting is a workshop for speculative networking research, so the proposal does not establish that these infrastructure guarantees are available today.
If chunk delivery becomes a network primitive, cleanliness and coherence could move from extraction APIs into the delivery layer. The standalone extraction category could partly dissolve. Freshness, reliability under adversarial conditions, and context shaping for downstream utility would remain necessary regardless of which layer provides them. For teams building now, the lesson is to evaluate the full path from the live web to the context window against all five criteria. The right choice is the one whose retrieval and output responsibilities match the application's needs, including the infrastructure the team is prepared to own.