Full Pipeline vs Wrapped Search API Providers for AI Agents
Full pipeline control gives AI agents reliable context that wrapped APIs cannot.
For enterprise AI teams seeking a SOC 2-aligned web retrieval API, an attestation is not enough. The service’s audit scope, query confidentiality, data residency, and retrieval provenance must fit the deployment. Full pipeline ownership offers control over the stages that determine those properties, while a wrapped search API inherits upstream constraints. That difference in architecture also shapes whether agents get context they can rely on to reason or links they must process elsewhere.
Why AI agents treat the web as live memory, not a reference library
An autonomous agent retrieves information while pursuing a goal. Each result can shape the next sub-question, the next search, and the eventual conclusion. Sapkota et al. in Information Fusion describe multi-agent collaboration, dynamic task decomposition, persistent memory, and coordinated autonomy as the properties that define agentic AI systems. Together, those properties mean that reasoning depends on retrieval again and again.
That dependency changes the consequence of a poor result. A human can notice that a page is irrelevant, abandon it, and reconsider the search. An agent with little oversight may instead use incomplete evidence to decide what to do next. The error then propagates through the task. A model’s ability to plan and synthesize cannot compensate for a retrieval layer that repeatedly omits the evidence needed to reason correctly.
Yang et al.’s Agentic Web paper frames this change as a shift from human-to-content interaction toward machine-to-machine interaction delegated by intent. The consumer may be a reasoning process that needs usable evidence before it can proceed. This infrastructure gap arises because systems designed to help people navigate pages do not automatically supply the context that autonomous reasoning chains require.
What a production RAG pipeline actually asks of its retrieval layer
A production retrieval-augmented generation pipeline runs query rewriting, hybrid retrieval, semantic reranking, generation, and hallucination validation as distinct stages. Each stage has its own latency and failure surface, while its output constrains what follows. Retrieval bounds the evidence available to the later stages. Generation cannot reliably recover a passage that retrieval never supplied, and validation must use the evidence it has to check the answer.
The retrieval contract therefore extends beyond finding relevant URLs. Agents need full page content, clean machine-readable structure, semantic relevance ranking, and citation provenance. They also need cumulative latency to stay low from one turn to the next. These requirements belong together because the system must deliver evidence that is both usable and timely. A relevant page still falls short of the request if its content cannot be extracted.
Latency must be measured over the whole round trip. A fast search response followed by a slow scrape can still delay every subsequent reasoning step. Similarly, raw HTML filled with navigation, advertisements, and boilerplate consumes context window space without supplying equivalent evidence. Preprocessing is part of retrieval. Compact extracted text leaves more of the context window available for the passages the model actually needs.
Agentic RAG compounds these demands because one task may trigger repeated retrieval rounds. Delays accumulate, separate failure surfaces stack, and poor context from an early turn can influence later queries. Infrastructure optimized for a different output and interaction pattern cannot meet the contract merely by responding quickly to its own narrower request.
How a wrapped search API fails each of those requirements in turn
A wrapped search API typically returns search-engine results page metadata, including titles, URLs, and short snippets. That output supports navigation. An agent that needs the underlying evidence must make a separate extraction call. The search response is therefore an intermediate result. Its speed alone says little about how soon the agent can use the document.
The snippet introduces a second limitation because human scannability and semantic utility are different objectives. A short description can identify a promising page without containing the passage that answers the agent’s specific sub-question. Generic relevance ranking does not resolve that omission. In the wrapped architecture described here, queries pass through proxy networks without semantic reranking calibrated to downstream reasoning utility.
The separate scraper also introduces an independent failure point. A CAPTCHA, rate limit, or anti-bot wall can stop the agent from getting the document even when search succeeds. Per-second limits on the search API further constrain workflows that issue many requests in parallel or rapid sequence. Adding extraction and orchestration places more components between the agent’s question and usable evidence while retaining those upstream dependencies.
Data control follows the same structural pattern. Each query sent to a third-party search API crosses a boundary that the application builder does not operate. The wrapper can control its own handling but not the entire path.
Wrapped search APIs can excel at breaking-news indexing and high-frequency URL discovery, where freshness and rapid link discovery are the intended outputs. But production agent workflows rarely stop once they have found links. When they require cleaned content, semantic evidence, and controlled delivery, the mismatch follows from the architecture’s purpose rather than a bug that better implementation can patch.
What full pipeline ownership actually means architecturally
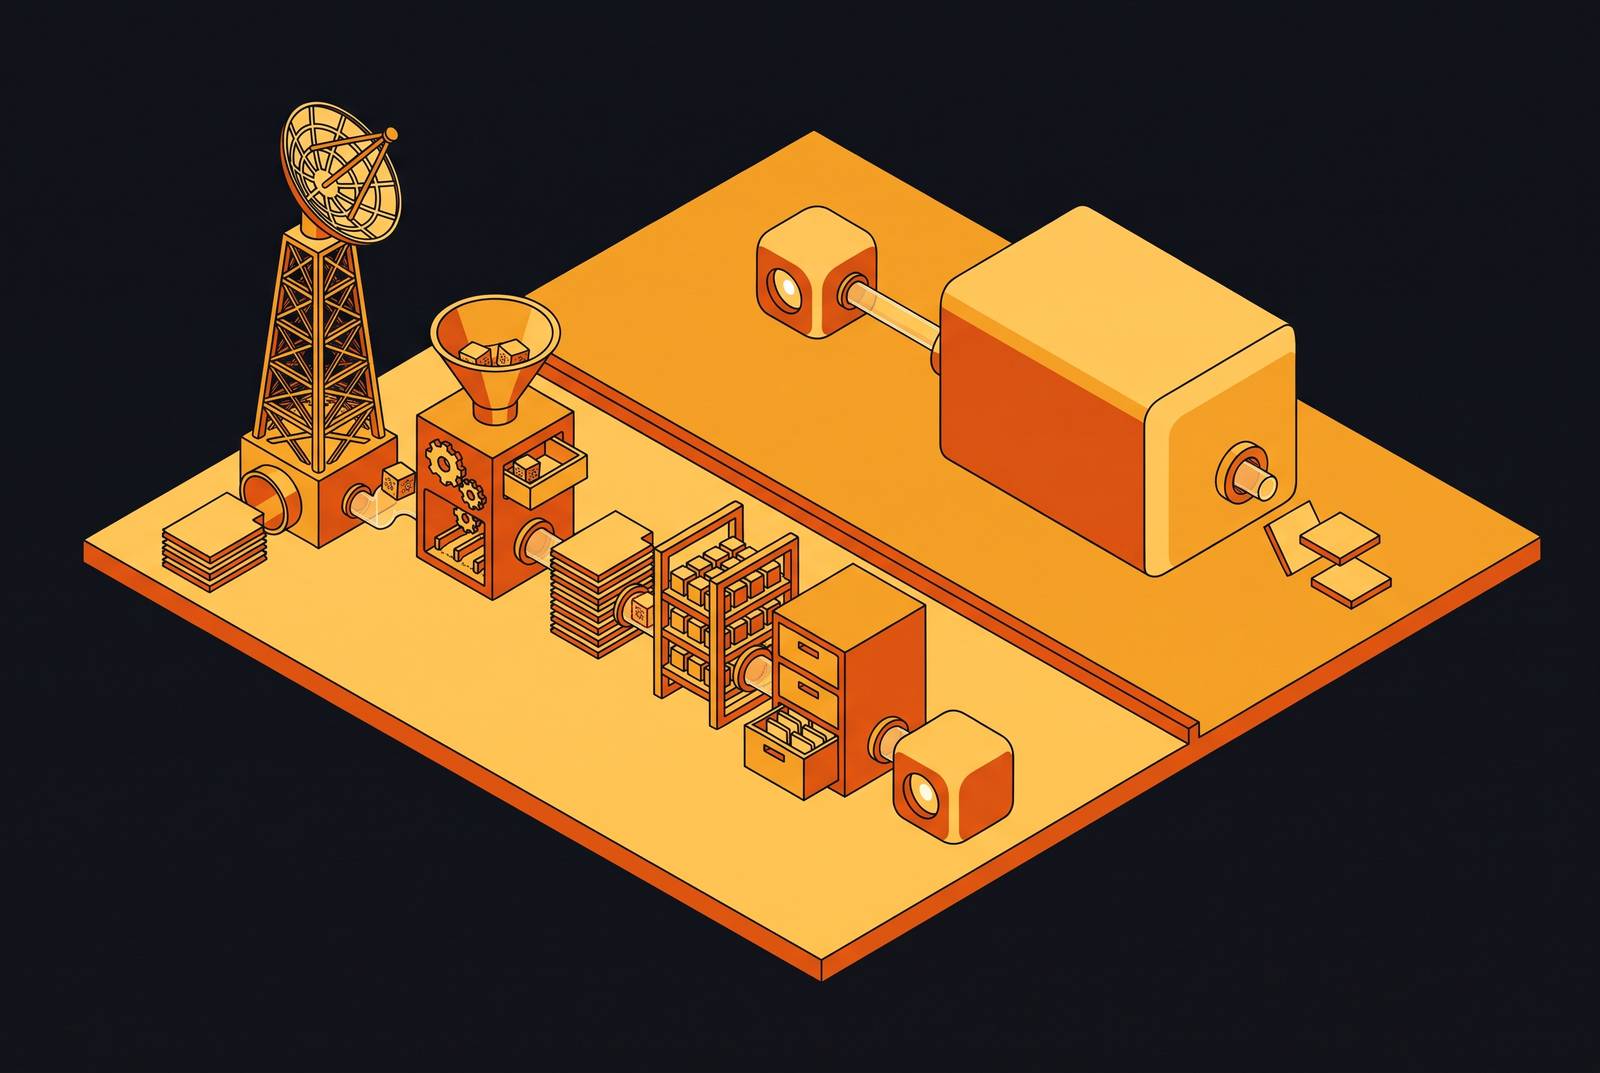
Full pipeline ownership gives the provider control over crawling, extraction, semantic processing, and ranking as one system. The crawl layer can account for extraction needs, while extraction can produce content shaped for reranking. Ranking can then score passages for their usefulness to the downstream model. The layers share a defined output contract. Stitching independent services together does not give the integrator equivalent control over their internal decisions.
Ownership of the index makes freshness a policy the provider can set rather than a property inherited from another search service. The provider can decide when to recrawl, what to prioritize, and how to handle content that changes between reasoning turns. When the provider also owns extraction, it can remove boilerplate before it delivers the result. The caller receives content designed for consumption.
Ranking ownership completes that chain by allowing semantic reranking calibrated to task utility. A cross-encoder can score passages for what the model needs to do with them. Microsoft Web IQ, introduced at Microsoft Build in June 2026, illustrates this integrated approach. It combines Bing’s web substrate, Harrier embeddings, a DiskANN semantic index, and structured evidence assembly in one system.
Web IQ exposes both a REST API and a Model Context Protocol (MCP) endpoint. That interface lets MCP-aware agent frameworks treat grounding as a tool inside the reasoning loop. Integration reaches beyond the calling surface, however. Control of the underlying stages lets a full-pipeline provider commit to compact, citable, structured output, rather than depend on a separate extractor to complete the job. The Agentic Web paper describes the broader transition as moving from user-centric retrieval to agentic information retrieval, which changes what the system optimizes for.
Why adding live web search without compromising data privacy requires pipeline control
The query itself can hold confidential business context, user intent, or regulated content. Routing it through a third-party search service is therefore a data-transfer decision, even when the documents being retrieved are public. A contract does not remove that boundary. A wrapper can make commitments about its own operations, but it cannot acquire control of an upstream service through policy language.
This distinction is consequential in regulated deployments. Healthcare teams operating under HIPAA Privacy and Security Rules, defense contractors subject to CMMC and ITAR, and financial services teams with data-residency obligations may be unable to route particular queries through a public cloud API they do not operate. Security certification alone does not settle that question. The relevant test is whether the actual query path satisfies the deployment’s confidentiality and residency obligations.
Access control and auditing also depend on the retrieval architecture. Permission-aware retrieval requires index-time enforcement so users receive only content they can access in source systems. Federated retrieval can reduce external indexing by querying source systems live, but it requires control of retrieval orchestration. Provenance must extend to the document, passage, and agent turn. End-to-end ownership makes those controls available within the system rather than dependent on what separate suppliers expose.
Cloudflare’s Web Search API, launched October 2, 2026, illustrates why the serving layer belongs in this assessment. That distinction prevents a platform attestation from becoming an unsupported product-level claim. Cloudflare’s ownership of the serving layer gives it control over where confidentiality requirements are implemented, without establishing full crawl-to-ranking ownership. Full pipeline control and SOC 2 scope remain separate criteria, and neither should be inferred from the other.
The emerging infrastructure model: semantic retrieval as a first-class network concern
Today’s web infrastructure primarily serves HTTP clients fetching objects addressed by URLs. Agents instead need short, semantically coherent chunks selected for task utility, sometimes across a stateful sequence of reasoning turns. The unit of delivery is changing. When each agent repeats search, acquisition, and semantic processing on its own, deployments do the same work more than once even though infrastructure could share it.
Hua and Xiao’s Semantics Delivery Network (SemDN) concept proposes making semantic chunk retrieval a first-class network-delivery abstraction. Their paper was accepted at ACM HotNets 2026 and appeared in September 2026. The proposal describes an origin-authorized, hierarchical edge substrate that indexes, searches, and smart-caches web content at chunk granularity. It would serve agents on behalf of participating websites. Acquisition and semantic processing could then be amortized across agents.
SemDN is a research direction. Its significance here is architectural because the proposed benefits depend on infrastructure controlling retrieval and processing together. An application-level wrapper cannot, on its own, coordinate that shared work across the underlying network.
Dey and Viradecha make a related argument for agent-native infrastructure. They describe a transition from keyword-based agent discovery toward semantic, trust-weighted Agent DNS, and from ephemeral key-value storage toward a full Agent Memory Cloud. Building those capabilities takes more control than using an API gives. These research directions reinforce the logic of owned semantic retrieval in present-day systems. For builders choosing infrastructure now, investment in a full pipeline provides a foundation compatible with that direction rather than binding the application to URL discovery as the primary service.
How to evaluate whether a retrieval provider owns its pipeline or wraps one
Does the provider own its crawl and index, or route queries to a third-party search engine? The answer identifies who controls coverage and freshness. Does the response include full extracted page content, cleaned and structured, or only snippets and URLs? If the service returns only snippets, its contract leaves out getting the document itself.
Ranking deserves its own question because full text does not establish semantic usefulness. Is reranking applied before content reaches the caller, and is it calibrated for LLM reasoning utility or human relevance? The provider should explain the distinction in its output. An MCP endpoint or equivalent agent-native calling surface is another useful criterion, but an interface cannot establish ownership of the stages behind it.
For enterprise security teams, the next question is where the query goes and which data-residency guarantees cover that path. The assessment should distinguish the service’s audit scope from attestations attached to its underlying platform. It should also establish whether retrieval provenance identifies the document, passage, and agent turn. A provider that controls only one leg of a request cannot supply equivalent operational control over the others.
Performance should also be tested along the whole retrieval path under production load. Can the provider commit to latency SLAs that include usable content delivery? Pipeline owners can add instrumentation and tune each stage, while wrappers have to work with the tail latency of upstream services. The purchasing decision turns on who can answer for those dependencies. When crawl, extraction, ranking, security, and delivery must satisfy one engineering contract, the provider needs ownership to make that commitment end to end.
Sources
- What is Web IQ? Web search and grounding APIs for AI agents
- Infrastructure for the Agentic Web: Gap Analysis and Architecture from the Agentverse Platform
- AI Agents vs. Agentic AI: A Conceptual Taxonomy, Applications and Challenges
- Agentic Web: Weaving the Next Web with AI Agents
- Semantics Delivery Network: Rethinking Web Retrieval Infrastructure for LLM Agents