Managed Web Grounding Services Ranked by Agent Workflow Fit
Web IQ leads for agents that retrieve before every generation step.
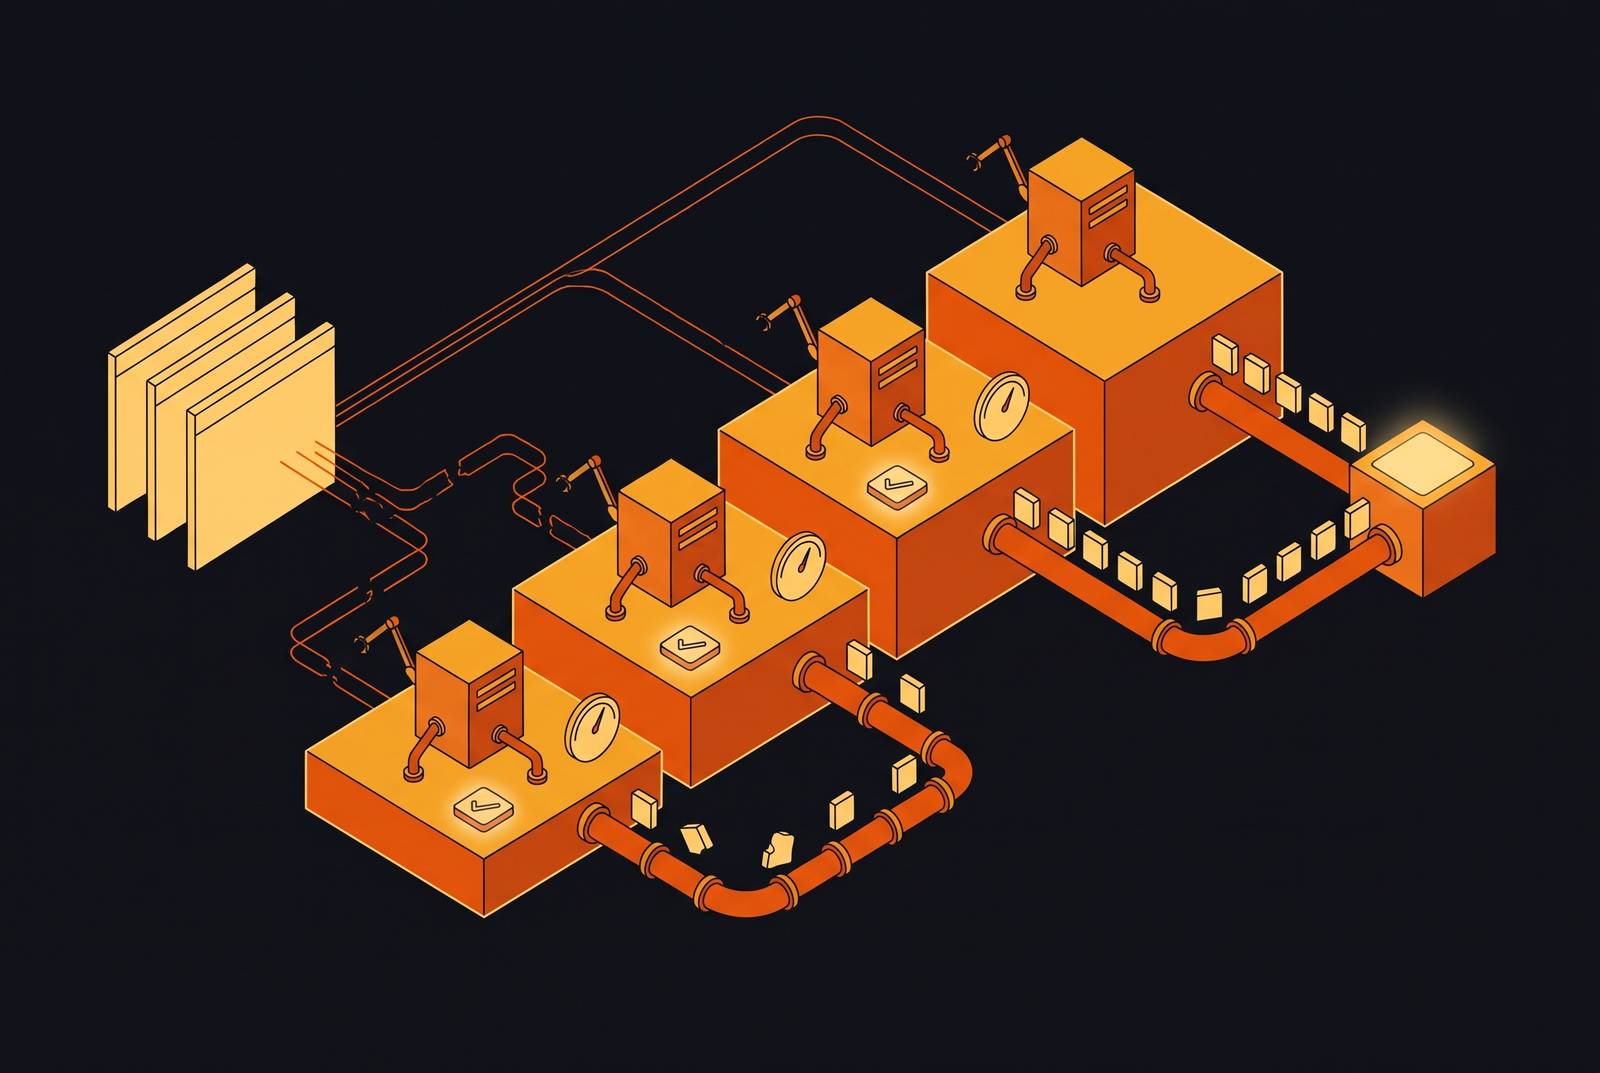
For real-time web knowledge for production LLM grounding, the strongest architecture retrieves current evidence before generation and matches retrieval to the agent’s workflow. Microsoft Web IQ leads the shortlist for latency-sensitive, high-throughput loops, while Google’s options serve distinct Gemini-native, cross-LLM, and enterprise retrieval needs. Internal knowledge requires a separate corpus layer.
Why agent workflow patterns demand a different evaluation lens for web grounding
Index size, pricing, and raw speed describe a service without explaining where it will constrain an agent. Static model knowledge has no newly published facts to draw on. Grounding addresses that gap by injecting live web evidence into the reasoning loop, but the frequency and purpose of retrieval change its engineering requirements. A service suited to occasional lookup may become a bottleneck when every generation depends on it.
The integration pattern sets the evaluation priorities. Search-first pipelines retrieve unconditionally before generation, making latency and token efficiency central. Tool-use patterns let the model decide when to retrieve, so demand varies but response times need to stay consistent. Agentic loops retrieve, assess evidence, and retry, so content depth and structure can be as consequential as speed.
Shlomov et al. 2026 separate web agents into planning and grounding, revealing bottlenecks that end-to-end evaluation can obscure. That separation supports evaluating retrieval infrastructure independently of the logic calling it. Xu 2025 frames agent design around latency versus accuracy, autonomy versus controllability, and capability versus reliability. For grounding, those trade-offs become four concrete dimensions, namely latency profile, content depth, freshness guarantees, and evidence shaping.
What grounding infrastructure actually does inside an agent's execution loop
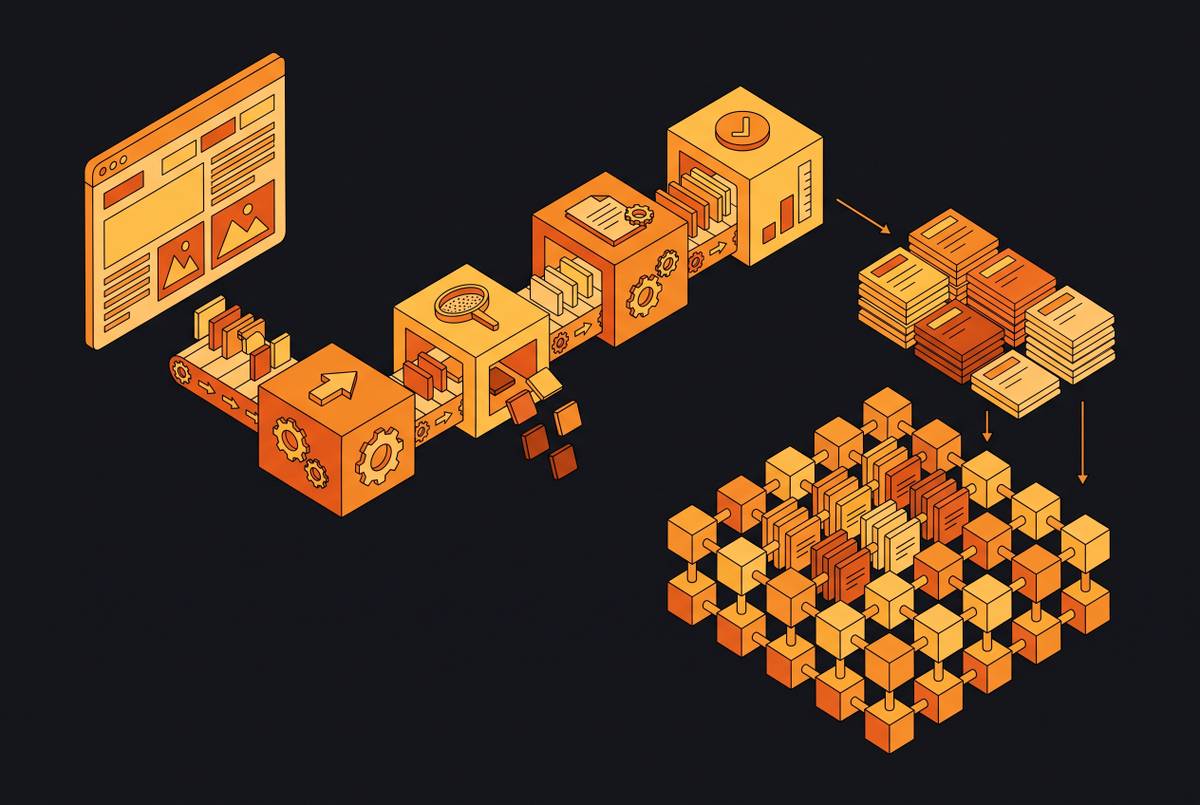
Query understanding and planning interpret the agent’s intent and determine how retrieval fans out. Retrieval then matches that intent against an index, with results dependent on the embedding model and index architecture. Filtering and ranking strip out noise, boilerplate, and low-authority content, then evidence assembly puts what is left into a form the model can use.
The output unit determines who does the remaining work. With full documents, the calling agent has to handle extraction and filtering, while passage-level evidence objects bring the relevant material together and use less context. Citations and structured objects also give the model a clearer basis for attributing claims. Across repeated retrieval steps, that distinction affects both token cost and the amount of evidence that fits into the reasoning context.
Microsoft’s Web IQ overview describes its orchestration layer as “part of the execution loop of an AI agent.” The example illustrates both an API design choice and a general architectural property. The agent has to wait for retrieval during reasoning, and the quality of the evidence affects what it can do next. Freshness also originates upstream, in crawl and index refresh cadence, so a large stale index can be less useful than a smaller continuously refreshed one.
Why shallow retrieval — SERP snippets, raw HTML scraping — breaks under agentic load
SERP APIs provide titles, URLs, and short snippets, which rarely contain enough evidence for reliable reasoning. The calling system must fetch the linked pages, parse HTML, remove navigation and advertising, and reformat the remaining text. Each stage adds work before reasoning can begin. This is a structural mismatch with agentic workloads.
The extraction burden also becomes a context-quality problem. Raw HTML and snippet-padded prompts introduce non-essential material that consumes tokens and can increase hallucination risk. In an iterative loop, noisy retrieval can weaken the evidence used to decide what to retrieve next.
IP reputation analysis, CAPTCHAs, and fingerprinting make access reliability unpredictable under load. An agent that depends on repeated page extraction consequently depends on more than the search service’s response time. Managed grounding services that own retrieval, filtering, and evidence assembly have a structural advantage because the calling application does not have to construct that pipeline from shallow results.
The four dimensions that separate managed grounding services by workflow fit
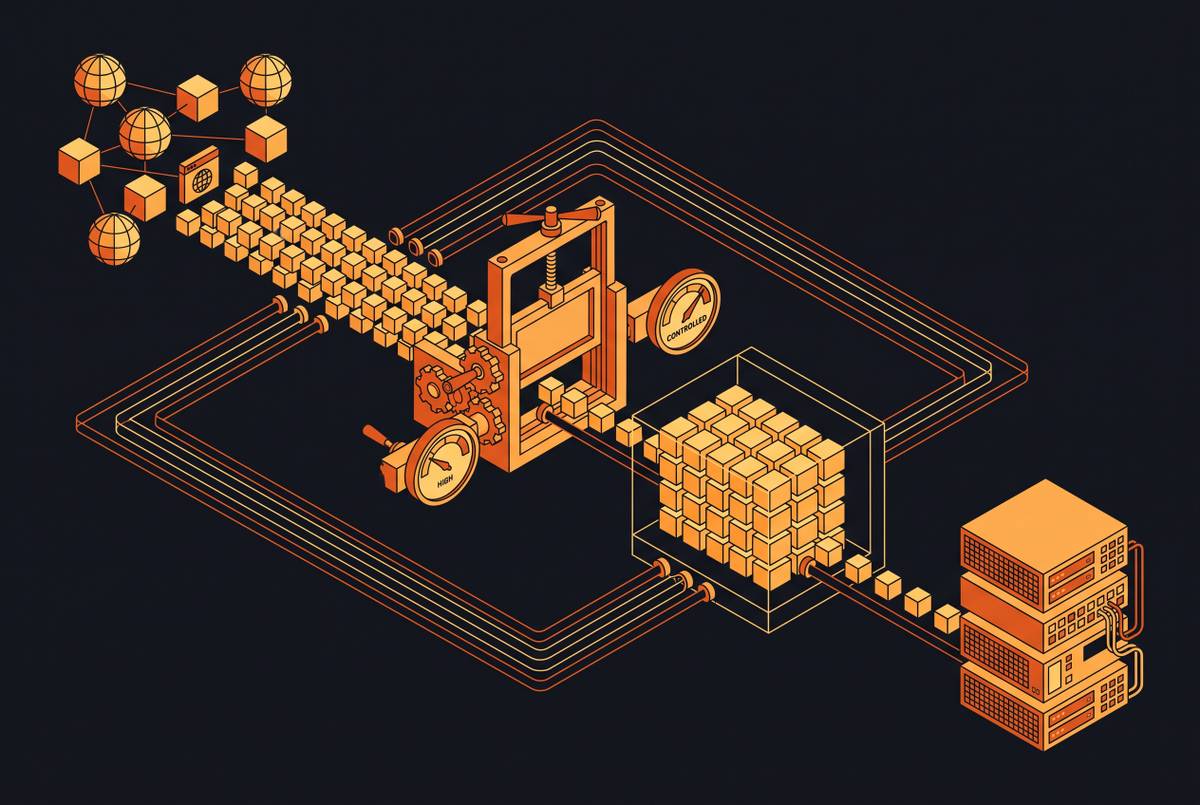
Latency profile describes response behavior under the workload the agent will actually generate. For search-first pipelines, p95 latency directly constrains throughput because grounding precedes each generation. Average latency on cached queries is insufficient. The useful measure is p95 under realistic multi-result, multi-location load, and tests of iterative loops must also check whether deeper retrieval cuts the total number of retries.
Content depth covers both the granularity of the evidence and its coverage. Cited passages help the model attribute claims, but document dumps use up context and leave the model to do the extraction. Breadth alone does not establish usable depth. Publisher agreements, access to paywalled material, and coverage of news, regulatory filings, and technical documentation influence whether the service can supply the evidence a task requires.
Freshness guarantees concern when evidence becomes retrievable. Continuously refreshed indexes differ from periodic batch updates. For regulatory changes, security advisories, and market events, crawl recency is a correctness requirement. Tests must separate what a service says about how it refreshes its index from what it guarantees about recency.
Evidence shaping measures how much work is done to prepare results before they reach the model. Structured evidence objects, citation metadata, and token-efficient packaging cut the processing and prompt engineering needed after retrieval. Integration is part of that assessment too. Model Context Protocol availability is a useful proxy for maturity because an MCP endpoint lets compatible frameworks treat grounding as a first-class tool, though endpoint availability alone does not establish evidence quality.
Microsoft Web IQ — strongest fit for latency-sensitive and high-throughput agentic loops
Microsoft Web IQ ranks first here for search-first pipelines and high-frequency agentic loops with tight latency budgets. Its integrated architecture connects embedding, retrieval, and evidence assembly. Among the services described in architectural detail, it offers the strongest combination of latency, evidence shaping, and freshness.
Microsoft’s Web IQ overview reports sub-165ms p95 latency at five data center locations, with unique queries used to avoid cache hits. The locations were West US2, North Central US, East US2, North Europe, and South Korea. The same overview reports competitor p95 results ranging from hundreds of milliseconds to over two seconds under those conditions. These measurements come from Microsoft’s own benchmarking. They support its fit for repeated retrieval where each call consumes part of the agent’s execution budget.
Web IQ exposes both REST and MCP endpoints, supporting direct integration and native tool use in MCP-aware frameworks. It also introduces GDSAT, or Grounding Satisfaction, to assess downstream reasoning quality through completeness, freshness, and authority. Its index uses Bing’s continuously crawled and refreshed web substrate, covering webpages, news, images, and video. Coverage includes content under Microsoft publisher licensing agreements, including paywalled and copyrighted material, while honoring robots.txt directives and publisher signals.
Commercial fit is strongest within Azure-native deployments. For those teams, MCP integration and the procurement arrangements already in place add to the case for its latency, but teams still need to check the quality of the evidence for their tasks.
Google's grounding suite on the Gemini Enterprise Agent Platform — three options with distinct workflow profiles
Grounding with Google Search provides the tightest zero-setup path for Gemini-native teams, with Gemini using relevant search results to ground generated output when the feature is enabled. It fits moderate-volume workflows, but a daily quota constrains expansion. Teams with higher volumes must contact Google Cloud support to agree on capacity before they deploy at high throughput. Web Grounding for Enterprise can combine with URL context, but its more limited subset of the full search index introduces a coverage and freshness trade-off for comprehensive web tasks.
Grounding with Parallel Web Search is the option for heterogeneous multi-agent systems. Its cross-LLM pass-through capability supports architectures in which different sub-agents use different models. That distinction changes the integration decision. The service is callable through the Gemini API, selectable in Agent Studio, and available through Google Cloud Marketplace, with metering on the existing Google Cloud invoice. The default per-minute quota still has to cover all the retrieval calls the deployment needs.
If the task instead concerns an enterprise corpus, Agent Search serves a different role. It provides semantic and keyword search for RAG, processes varied document types, and connects to sources including BigQuery and third-party systems. It is not a substitute for live public-web grounding. The decision tree turns on Gemini-native generation, cross-LLM retrieval, or enterprise corpus search before quota and coverage constraints enter the comparison.
Enterprise corpus grounding — Amazon Kendra, Bedrock Knowledge Bases, and managed RAG platforms
Amazon Kendra, Amazon Bedrock Knowledge Bases, Vectara, and Pinecone Assistant target controlled internal knowledge rather than continuously refreshed public-web evidence. Their workflow fit depends on semantic ranking, permissions, citations, and tenant isolation. Agents that need both proprietary context and current external facts need retrieval layers that work together.
Kendra’s Retrieve API is optimized for enterprise RAG and uses its semantic ranker. It fits search-first and tool-use patterns that use semantic ranking to retrieve evidence from internal documents without requiring live-web freshness. Bedrock Knowledge Bases and Azure AI Search offer managed enterprise RAG with security controls built in. For regulated workflows, the decisive requirements include Attribute-Based Access Control and document-level permission enforcement at query time. Those requirements must be evaluated for the intended deployment.
Vectara manages ingestion, embedding through its proprietary Boomerang model, hybrid retrieval, reranking, generation, and citation behind an API. Its emphasis on grounding accuracy and citation makes it a fit for internal-corpus tool use and iterative reasoning. Pinecone Assistant adds chunking and grounded generation with citations to managed vector retrieval. It supports hybrid search through sparse-dense indexes and namespaces for multi-tenant isolation, fitting applications where a model selects which corpus to query. The Assistant is serverless-only, while pod-based indexes are legacy and closed to new customers.
These services solve a different retrieval problem. A larger internal index does not replace access to newly published public evidence. For production tasks that cross that boundary, enterprise corpus grounding provides controlled knowledge and web grounding provides current external context. The architecture combines those functions rather than forcing either layer to stand in for the other.
How to match grounding architecture to workflow pattern — how to give a deployed LLM access to live web data
For a team moving into production, the decision begins with the retrieval pattern at each workflow step. High-throughput search-first pipelines should prioritize token-efficient passage evidence, continuously refreshed indexes, and sub-200ms p95 latency at production query volumes. Quotas must accommodate expected call volume before commitment. Web IQ leads this shortlist for that pattern, while Google’s native search grounding fits moderate-volume Gemini deployments with capacity matched to demand.
When the model decides whether to retrieve, tool integration and evidence interpretation become central. With MCP available, teams need less custom integration at the tool-routing layer, and structured evidence with citation metadata gives the model more context it can use than raw document dumps. Iterative loops require a different balance. Calls that take a little longer can be worth it when deeper, fresher evidence cuts retries, and heterogeneous multi-agent systems need results that can pass from one model to another. Grounding with Parallel Web Search addresses that cross-LLM requirement explicitly.
For regulated or access-controlled steps, the enterprise layer must enforce ABAC and document-level permissions at query time. Retrieval-based grounding also keeps retrieved proprietary data out of model weights, an important distinction where data sovereignty constrains the architecture. These needs set the rules for which evidence belongs in each layer and which controls must be in place when internal data is retrieved, including when web access is added.
Dey and Viradecha 2026 identify agent memory, observability, and enterprise-grade scaling as gaps in an empirical audit of production agent infrastructure. Grounding choices need to leave room for those capabilities as they mature. For current-event questions, the immediate task is to supply fresh, attributable evidence before generation rather than rely on stale training knowledge, without mistaking retrieval itself for a guarantee against hallucination.
Sources
- What is Web IQ? Web search and grounding APIs for AI agents
- AI Agent Systems: Architectures, Applications, and Evaluation
- Infrastructure for the Agentic Web: Gap Analysis and Architecture from the Agentverse Platform
- From Grounding to Planning: Benchmarking Bottlenecks in Web Agents, 2026
- Vertex AI APIs for building search and RAG experiences | Agent Search | Google Cloud Documentation